Category Archives: AI

The Amnesia Cycle and Why AI Is Turning Developers Back Into Testers

I started working in technology around 1993. One of my first jobs was in quality assurance, partly because there was no security profession to join yet.

There were people doing the work, but few companies were hiring for it. That changed within a decade. Until it did, people with the instincts that would later define security engineering landed in adjacent disciplines. Test was one of them.

That was true for me. I became a test manager fairly quickly, later worked as a test architect, then went on to software development, security, and a bunch of other things.

More than thirty years later, I find myself watching something funny happen.

AI is turning software developers back into testers.

Not the kind of testers we were in 1993. What it means to test software has changed several times since then. But at a more abstract level, the work is surprisingly familiar.

The person is no longer primarily producing the thing. They are increasingly trying to determine whether the thing that was produced is any good.

And we have been around this loop before.

We develop a specialty because a problem is hard. We get good enough at it to encode pieces of the expertise into process, tools, and automation. Eventually the machinery works well enough that the underlying expertise starts to look unnecessary. We distribute the responsibility, automate more of it, and convince ourselves that the problem has largely been solved.

Then the system grows, the environment changes, or a new technology arrives and exposes all of the judgment that never made it into the machinery.

The responsibility never left. It just changed costume.
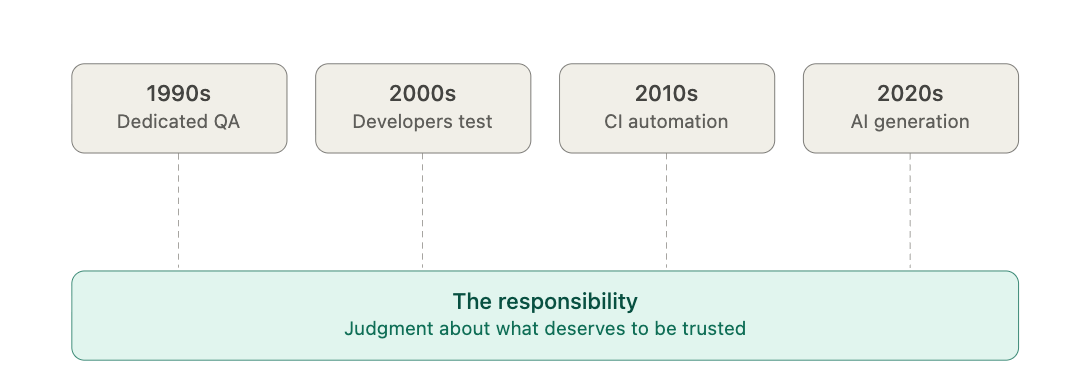
When testing was a profession

In the 1990s, software development and software testing were much more clearly separated. Developers wrote software. Test organizations tried to figure out where it broke.

A lot of the work was manual. People installed builds, exercised features, constructed strange states, tested boundaries, wrote bug reports, and tried to reproduce failures. By modern standards, much of it would look labor-intensive. Some of it really was scut work.

But the separation had an important organizational property. The person who built the thing and the person whose job was to find out why it was wrong were different people.

Their incentives were different too. Developers were trying to make the product work and get it shipped. Testers were rewarded for finding the circumstances under which it did not work.

Those are complementary responsibilities, but they are not the same responsibility.

Over time, testing acquired a status problem. It was increasingly treated as work that did not require the same level of engineering skill as implementation. One response was to give more of it to junior developers.

Then we moved further. Instead of a separate organization owning quality, developers would test their own software.

Much of that change was good.

Unit testing was good. Test-driven development was good. Continuous integration was good. Automated regression testing was good. Testing closer to the point where software was written eliminated entire classes of expensive downstream failures.

The nature of testing changed too. It moved away from a model dominated by manually exercising a finished product and toward one where tests could become part of the way software itself was specified and constructed.

So the story is not that we eliminated QA and that was simply a mistake.

The mistake was gradually convincing ourselves that because we could automate more of the mechanics, we needed less of the judgment.

A test that passes is not evidence that the system is good

As automation improved, we became extraordinarily good at running tests.

A modern software project can execute tens of thousands of tests on every change. We can measure coverage, reject regressions, test configurations, fuzz interfaces, spin up entire environments, and tear them down again without anybody touching them.

The machinery works.

But there is a distinction that became easier to overlook.

A test can work perfectly and still tell you almost nothing useful about the quality of the system.

The hard question is not always whether the test passed. It is whether passing that test is evidence of the property you actually care about.

That gets harder as systems become more complicated. A system can have an enormous green test suite while failing in a way nobody thought to represent in the suite.

There is an important difference between mechanical verification and judgment about what deserves to be verified. One asks whether the checks we wrote passed. The other asks whether those were the right checks.

Automation became exceptionally good at answering the first question. It did much less to eliminate the difficulty of the second.

A test suite is an encoding of somebody’s model of how the system can fail. It captures the failures we anticipated, the properties we chose to represent, and the assumptions we knew enough to challenge.

It says much less about the failures nobody imagined.
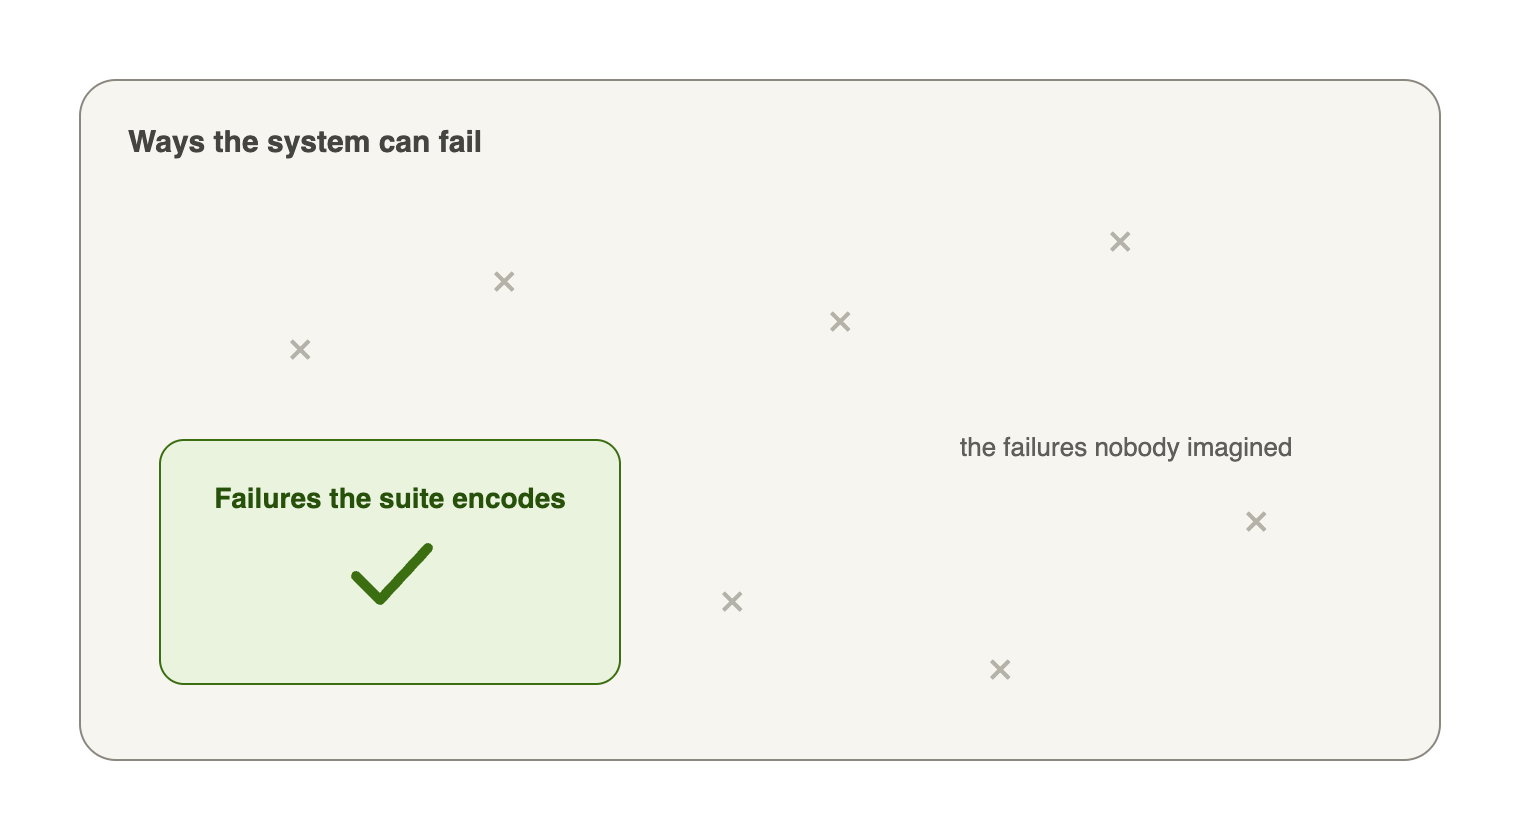
Automation did not eliminate the test problem. It moved the test problem up a level.

The scarce skill became figuring out what to test, what failure looks like, which assumptions need to be challenged, and what evidence should actually make us confident in the result.

That is why what is happening with AI feels so familiar.

We thought AI would do the testing

One of the obvious expectations around generative AI was that it would automate still more testing.

If the AI can write the implementation, it can certainly write unit tests too. And it can.

But that misses the more important change.

AI is making implementation cheap.

A developer can already cause far more code to be produced than they could reasonably have written themselves. As agents improve, that multiplier gets larger. It is not difficult to imagine one engineer directing dozens, hundreds, or eventually thousands of concurrent software-producing processes.

At that point, traditional code review is not merely inefficient. It becomes physically impossible.

Nobody is going to carefully read every line produced by a thousand coding agents.

The generated output is also not quite like the output of an old deterministic compiler or code generator. These systems are probabilistic. Run them again and you may get a different implementation, a different decomposition, or a different mistake.

That makes the old assumption that we can inspect the artifact into correctness even less plausible.

So the human moves up a level.

Instead of spending most of the time constructing the implementation, we increasingly construct the conditions under which an implementation will be accepted. We write tests, evals, invariants, acceptance criteria, adversarial cases, and constraints. We decide what evidence is sufficient to tell us that the machine-produced result is actually good.

Software developers are becoming testers again.

It is not 1993-style manual QA. It is closer to specification, TDD, evaluation design, systems validation, and the construction of executable evidence.

But abstractly, it is the same work happening in a different way.

The form changes. The responsibility does not.

What the new testing actually looks like

The easy question is whether generated code passes the existing test suite.

The harder question is whether the suite represents the properties we actually care about.

Does the generated component behave correctly under inputs we did not anticipate? What happens when independently generated components interact and two locally correct decisions compose into a globally bad result? What happens after the system has been operating for days, accumulating state and acting on the consequences of its own earlier decisions?

What happens when the environment differs from the conditions represented in our evals? And what happens when an adversary deliberately searches for the assumptions we failed to encode?

Those questions are not answered by producing more tests mechanically.

They require somebody to form a theory of failure.

The scarce skill is increasingly understanding the mechanics of failure. That means knowing where the system boundaries are, which properties must remain true across those boundaries, what assumptions are hidden inside the architecture, and how reasonable local behavior can produce unreasonable global outcomes.

It also changes what a useful test looks like.

When implementations are relatively stable, testing specific examples can tell you a lot. When an AI can regenerate the implementation tomorrow, durable properties become more important. The question shifts from whether this implementation produces the expected result for this input toward which properties must remain true across whatever implementations the system produces.

Those properties might concern correctness, authority, state transitions, isolation, safety, or the relationship between components. The implementation can change while the invariant remains.

That is a different kind of leverage.

Verification also stops neatly ending at release. Some failures only emerge through interaction with real environments, long-running state, changing inputs, or behavior that was not represented during development. That pushes part of the evidence gathering into operation through telemetry, observability, runtime checks, and the behavior of the deployed system itself.

The new tester is therefore not just checking whether an implementation conforms to a specification somebody else already wrote.

Increasingly, they are responsible for deciding what the specification must say, which properties must survive implementation changes, which failures matter enough to detect, and what evidence is sufficient for the resulting system to deserve trust.

That is a substantially higher-order form of the same old responsibility.

High-quality scut work

There is a funny status inversion hiding in this.

Test used to be treated as scut work. Then we gave more of it to junior developers. Then we told every developer they were responsible for doing it themselves. Then we automated as much of it as we could.

Now we are automating the part we used to think was the prestige work, writing the software, and leaving the developer sitting above the machinery trying to determine whether any of what it produced is good.

We may have turned one of the industry’s prestige jobs into very high-quality scut work.

The funny part is that the scut work may now be where much of the value lives.

When implementation is expensive, the person who knows how to implement something is scarce. When implementation becomes cheap, the scarce person is the one who knows what should be built, what properties it needs to have, how it is likely to fail, what assumptions are hidden inside it, and what evidence would convince us that it works.

Generation gets cheaper. Judgment does not.

Security already did this

I have seen almost the same cycle happen with security.

In retrospect, it is probably not an accident that so many early security people came through test. Both disciplines train you to look at a system somebody else believes works and ask what they have failed to consider.

Testing asks how the behavior can violate what was intended. Security asks how trust, authority, or assumptions can be violated even when the system appears to be functioning normally.

Both reward a certain kind of skepticism.

When I started, security engineering barely existed as a normal software profession. By the late 1990s it was becoming one. By the early 2000s, it was clearly a distinct industry with dedicated teams and career paths.

That specialization happened because security was hard and ordinary development organizations were not consistently good at it.

Then we started saying something that was also fundamentally correct. Security should not be something another group bolts onto the product afterward. Developers should build secure systems themselves.

“Security is everyone’s responsibility.”

There is nothing wrong with that principle.

The problem is what happens when we confuse responsibility with expertise.

A product developer is trying to ship a product. They have schedules, features, performance requirements, compatibility issues, reliability problems, customer demands, and dozens of other things competing for attention.

Security becomes one of many things they are supposed to get right.

When that proves insufficient, organizations build machinery around the problem. We add secure development lifecycle processes, scanners, policy gates, paved-road platforms, and controls designed to make the safe thing easier than the unsafe thing.

All of those things can help.

But notice what we are doing.

After deciding the specialist function should be distributed into the rest of engineering, we are encoding pieces of that specialist judgment back into systems and processes.

A scanner encodes somebody’s knowledge of what a vulnerability looks like. A secure-by-default platform encodes somebody’s judgment about which choices should be permitted. A policy gate encodes somebody’s model of what conditions need to hold before software should be released.

The specialist may become less visible as that expertise gets embedded into the platform, but the expertise did not cease to exist. It became infrastructure.

Eventually there is enough machinery that it again becomes tempting to ask whether we really need the specialists.

Then the abstraction leaks.

A threat appears outside the model encoded in the scanner. A platform assumption no longer holds. A new system does something the existing governance framework was never designed to reason about.

Then we discover that we automated the known answers, not the ability to recognize new questions.

AI security and the latest rediscovery

AI makes this pattern almost comical because we are currently rediscovering old classes of security problems with new names.

Prompt injection is obviously not literally SQL injection. The implementation is different, the interpreter is different, and the failure modes are different.

But someone who spent the 1990s and 2000s dealing with SQL injection, command injection, script injection, confused deputies, trust boundaries, privilege separation, and the consequences of letting untrusted input become control should find the family resemblance hard to miss.

We have spent decades learning that you should be very careful when information from an untrusted party can influence what a privileged system interprets as instructions.

Now we have built enormously capable interpreters whose primary interface is natural language. We mix instructions and data in the same context, connect them to tools, and act surprised when hostile input changes what they do.

The technology is new. The institutional failure mode is not.

The same thing is happening in conversations about containment and sandboxing. We are once again discovering that powerful systems need boundaries, that those boundaries need to be enforced rather than merely described, and that capabilities should be constrained by something stronger than an instruction asking the system to behave.

None of that makes AI security trivial. The new systems create genuinely new problems. But novelty at one layer does not erase the accumulated lessons at another.

We knew versions of these things thirty years ago. What keeps recurring is not the exact vulnerability. It is the belief that a new abstraction has somehow relieved us of the old responsibility.

That is where the amnesia comes in.

The amnesia cycle

You could describe the pattern as specialization, codification, automation, perceived redundancy, loss of judgment, scaling failure, and rediscovery.
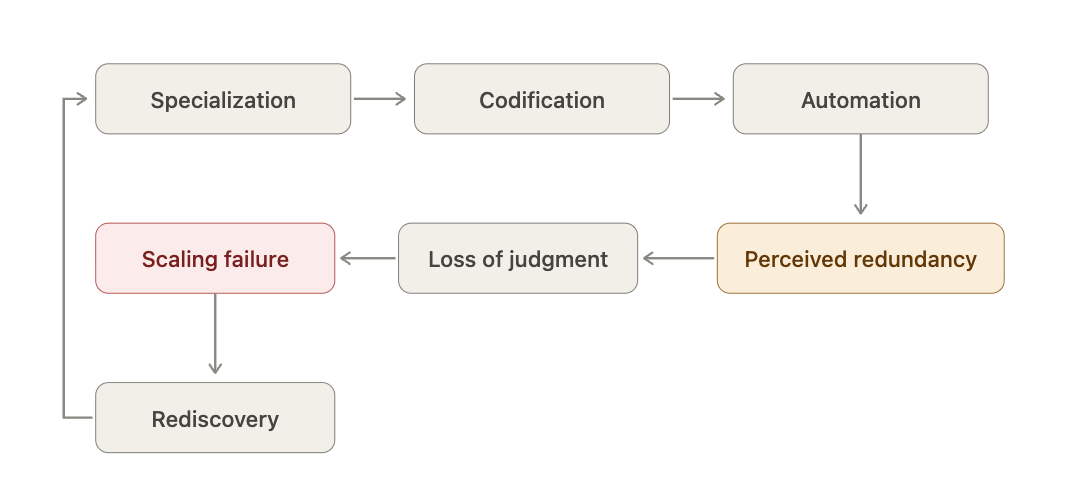
That is the amnesia.

We rarely forget the artifacts of the previous generation. We keep the test frameworks, scanners, development processes, controls, and automation.

What we forget is why the people who created those things thought the problem was hard in the first place.

Eventually we confuse the existence of the machinery with possession of the expertise that created it.

A passing test suite becomes evidence of quality. A security scanner becomes evidence of security. An AI eval becomes evidence that the AI is doing the right thing.

Until the system moves outside the assumptions those mechanisms encode.

Then the old problem appears again, wearing different clothes.

The responsibility never leaves

That is the through line I see between testing, security, and what is now happening with AI-assisted development.

We are very good at abstracting away mechanics. That is what engineering does.

But when we successfully automate the mechanics, it is easy to convince ourselves that we automated the underlying responsibility too.

We did not.

Testing did not disappear when the dedicated QA organization disappeared. Security did not disappear when we made it everyone’s responsibility. Verification will not disappear because an AI can generate both an implementation and a test suite that says the implementation is fine.

Somebody still has to decide what “fine” means. Somebody has to recognize the assumptions the automation does not know it is making. Somebody has to decide which failures matter. Somebody has to determine what evidence would falsify the claim that the system is working.

Somebody has to distinguish a system that successfully passes its tests from one that deserves to be trusted.

The responsibility never leaves. It changes costume.

I started my career in a world where developers wrote the software and people like me tested it. We spent the next thirty years treating test first as work developers should not have to do, then as work developers should do themselves, and finally as work machines should increasingly do for them.

Now the machines are starting to write the software.

And the developers are increasingly responsible for figuring out whether any of it is good.

Apparently the tester won.

Hurst University

For as long as my children can remember, I have told them that they are students at Hurst University.

It has no campus, no accreditation, and no admissions process. Joining the family is enough to get you enrolled. Graduation is another matter.

There is only one requirement. By the time you leave the house, you should be capable of building a future for yourself.

I don’t mean that you should know what you are going to do for the rest of your life. That is one of the stranger questions we ask young people. Most adults I know have changed direction enough times that pretending an eighteen-year-old is making a permanent occupational choice is unserious.

What I mean is more fundamental. You should know how to learn, and you should know how to work. When you encounter something you don’t understand, you should have some idea how to get from ignorance to competence. You should know how to take a hit without deciding the hit defines you, how to recognize when your assumptions were wrong, and how to change direction without treating everything behind you as wasted.

Most importantly, you should increasingly understand that the responsibility for what happens next belongs to you.

That is Hurst University.

There is nothing new about the idea. If anything, it is an old model of education with a family name attached to it.

For most of human history, becoming educated and becoming useful were close to the same thing. Children watched adults do real work. Then they helped. Then they were trusted with some small part of it. They made mistakes where mistakes were survivable, were corrected by somebody who knew more than they did, and tried again. As competence increased, the work got harder and supervision got lighter. Eventually the person who had been taught became somebody who could be trusted to act without waiting to be told what to do next.

That transfer is the part I care about most. The student eventually has to become responsible for the education.

I learned that the hard way, and then I had to watch one of my children learn it too.

He was not slow. He was seeking out serious material for pleasure at an age when adults found it surprising. But the way he took in information did not match the way the school delivered it, and the instruments the school trusted returned the wrong answer about him. The system then acted on the wrong answer. He began to notice he was being handled as a different kind of student, and he could not work out why.

The part I remember is not the meetings. It is that he started to wonder whether the school knew something about him that he didn’t.

I eventually moved him somewhere more willing to respond to an individual child, which helped. The more important intervention was a conversation.

I told him what I believed to be true. No institution was ever going to be able to take full responsibility for his education. Some things were going to be harder for him than for other people, and that was not going to change.

Then I told him that his challenges were his superpower.

I meant it literally, and I explained why. Most people are never forced to learn how they learn. They get through on the method they were handed, and they only discover its limits much later, if ever. He was going to have to build his own method starting now, at nine, because the handed one did not work for him. That is a brutal assignment and it is also an enormous head start. The world keeps rewarding people who can acquire what they need without being given it, and he was going to be practicing that while everyone else was still being taught.

Then I told him he was a student at Hurst University, and that when he graduated from this house he was going to be fine.

He is grown now. In his twenties he built a business and sold it to one of the largest financial services companies in the world, which is a thing you cannot do without becoming a fast and relentless student of whatever is in front of you. Entrepreneurs are not people who already know how. They are people who find out in time.

He is one of the sharpest people I know and one of the most prepared, and the second of those is the one he built. He worked out early that being the smartest person in the room and being ready for the room are different things, and that only one of them was under his control. He stopped waiting to find out which he would get. That habit came out of the friction, and I am not sure anything else would have produced it.

I was a student at Hurst University long before I had a name for it.

I was dyslexic and dysgraphic and did not present well to the educational system. At one point my parents were told they should prepare themselves for the possibility that I would never be capable of supporting myself.

That prediction did not age well.

I went to college young and moved out at sixteen. Some of that was rebellion, but mostly I wanted independence in the literal sense. I wanted control over my own life, including the economic responsibility that came with it.

A lot of my education after that happened without anybody designing it. Computers gave me problems I cared enough about to solve. Programming led into systems. Systems led into networking. Networking led into security. Security eventually required understanding companies, incentives, law, economics, organizations, and people. I kept encountering things I did not know and learning enough to get through the next door.

One capability created a reason to acquire another.

None of it started with me.

My father grew up on a subsistence farm, where you fix what breaks with what is in the barn because the alternative is doing without. He taught himself rocket chemistry as a kid off that same principle and was working on satellite hardware by his early twenties. I have written about him before, so I will not tell it twice.

What matters here is that he never called any of it an education. It was just what you did when you needed to know something.

So I did not invent this. I inherited it, gave it a name, and made the handoff deliberate. That last part is the part that matters, because none of it moves on its own. It has to be handed over on purpose, by somebody who decides to bother.

Years ago, when I wrote about apprenticeship, I described four things that had mattered enormously in my own development: access, direction, challenges, and support. I still think that framework is right, but I now see something underneath it. Those are not merely the ingredients of a good apprenticeship. They are the ingredients of an environment that gradually teaches someone to direct themselves.

Give somebody access to things worth learning. Put people around them who know more than they do. Give them problems slightly beyond their current ability. Support them enough that failure remains recoverable. Then, slowly, stop telling them what to do next.

That last part is the actual transfer.

Having three children made this clearer, because the same philosophy looks completely different depending on the student.

My second child has always worked. At four he was doing long division and by 6 or 7 he could recite the major bone and muscle groups. As a teenager he became a nationally ranked fencer, which is not something that happens to a person for being quick. It happens through years of drilling the same movement badly until it is good, losing in front of people, and going back the next day.

So the story I used to tell myself about him, that things came easily and he had therefore never built the habit, does not survive the evidence. He built it early. He built it in a domain nobody assigned him.

What was true is that school rarely asked him for it. He was admitted to several of the best aerospace programs in the world and ultimately chose computer engineering, and he is now somewhere the standard is set by people who are also very good and where thinking fast is the baseline rather than the edge.

So what I am watching is not a young man learning to work. It is someone moving a work ethic he already owns out of the place he first built it and into the place he intends to live. That transfer is the entire point of this essay, and he is doing it in front of me.

My third is different again. Nearly all of her identity is currently organized around a single competitive sport, roughly twenty-six hours a week of it. That is not a complaint. Twenty-six hours a week of anything difficult teaches repetition, correction, pain tolerance, delayed gratification, and performing while people watch. The work ethic already exists.

The problem is that she believes the work ethic belongs to the sport. Her brother has already shown that it doesn’t, which is the most useful thing an older sibling can do.

Activities end. The machinery that produced the excellence should travel.

Aptitude changes the educational problem. It does not remove the educational problem.

A child who struggles may need to learn that difficulty is not the same as inability. A child who rarely struggles may need enough friction to discover the value of preparation. A child who becomes excellent in one domain may need to discover that excellence is partly a process that can be carried elsewhere.

The curriculum changes because the student changes. The goal does not.

The goal is agency. By agency I mean the ability to encounter something unfamiliar and say, with some credibility, “I don’t know how to do this yet, but I know how to begin.”

That may be the most durable thing an education can produce.

My father was not the only one. My mother was doing the same thing in a different register, and I was even slower to see it.

She started as a hair stylist. Later she became a tool-and-die worker at Boeing. Then she moved into knowledge work and eventually retired as a business analyst.

Described by job title, those look like unrelated careers, the sort of résumé that gets read as drift. Described by behavior, they are the same story repeated several times. She kept becoming qualified to do things she had not previously known how to do.

Nothing about cutting hair prepares you to hold tolerances on a machined part. Nothing about machining prepares you to take apart how a business actually works and put it back together as a requirement. What carried across was not the content. It was the practice of arriving somewhere without the necessary knowledge and acquiring it in public, in front of people who already had it, while the work still had to get done.

She did that at least three times, each time later in life than the last, each time with more to lose. Watching it happen taught me more than any explanation of it would have.

I think we put far too much weight on occupational identity. We ask people what they “are” when what we mean is what they are being paid to do right now. Those are not the same thing.

A mechanic who becomes an engineer does not arrive empty-handed. A construction worker who moves into software already understands sequencing, dependencies, tolerances, physical constraints, customers, mistakes, and what happens when plans encounter reality. A salesperson who becomes a product leader knows things about incentives and people that do not appear in a product-management textbook.

Learning one serious domain teaches you more than the facts of that domain. It teaches you something about systems, and, if you are paying attention, something about how you yourself become competent.

That is why the question “What are you going to do with your life?” is not useful. Ask instead what you are going to do next.

You are not choosing forever. You are choosing next.

That does not make the decision unimportant. It changes what makes the decision good. A good next step should leave you with more than you had before. More competence, more judgment, more context, more relationships, more credibility, more capital, or simply more options.

Then you choose again.

This is also why I have never been comfortable with “follow your dreams” as career advice. Dreams are useful. They give us energy and they make us try things. But desire and strategy are not the same thing.

People have aptitudes whether we like that fact or not. The world has needs whether we like that fact or not. Some capabilities are scarce, some are common, and some interests map more naturally than others onto work that can support a life. If you expect something to support your life, understanding how it creates value is part of taking responsibility for the decision.

Years ago I was riding the gondola between the peaks at Whistler with three young women. One of them had recently graduated and was telling the others about an argument she had had with her boss. She had a degree now, and she thought she should be paid more. Her boss told her he could not pay her more simply because she had acquired the degree.

She was furious. Why had she bothered getting it?

Then, somewhere in the conversation, she mentioned that she worked at a sandwich shop.

I never learned what the degree was in. That is probably why the story stuck with me. The degree may have been enormously valuable, and may have opened an entirely different career a month later. But the credential itself had not changed the economic value of the work she was performing that afternoon.

The point is the distinction between learning something, possessing evidence that you learned something, and becoming capable of doing something the world values. Those things overlap, but they are not identical.

Eventually reality gets a vote.

That phrase matters to me because it applies well beyond credentials. You can believe you understand a system until you have to build one. You can believe you understand customers until you have to sell something to them. You can believe you understand leadership until somebody else’s livelihood depends on your judgment. You can believe you understand risk until the decision is yours and the consequences arrive with it.

Capability develops when knowledge begins colliding with consequence.

That is why work, projects, apprenticeship, competition, and responsibility matter so much. They are not simply places to apply learning. They are part of how learning becomes judgment.

And judgment is difficult to acquire without being wrong.

My father used to ask, “Do you know why God made young men so stupid?”

“So they could do the impossible.”

He usually said it about the early space program, and that was not a coincidence. The young men in the joke were him and the people he worked with. He was not describing a category of person. He was describing a room he had been in.

There is a limit to the principle. Ignorance can get you killed. But experience accumulates reasons a thing will not work, and there is a danger in becoming so sophisticated about risk that the sophistication becomes a reason never to take one.

If you are going to attempt difficult things, some of them will not work. What matters is what happens next.

Failure itself is not automatically useful. Failing repeatedly without changing anything is repetition. The useful part is the loop afterward. What happened, what assumption was wrong, what did I misunderstand, what was inside my control, and what should change next time?

The attempt failed. That is information.

“I am a failure” is something else.

Rejection works much the same way. Many worthwhile things require volunteering for outcomes somebody else partly controls. Apply for the job. Ask for the opportunity. Pitch the customer. Publish the idea. Start the company. Compete.

Somebody gets to say no.

If no is psychologically intolerable, you eventually begin designing your life so nobody ever gets the opportunity to say it. That feels safer, but it also shrinks the range of possible futures.

This is why resilience is less something you explain to a child than something you progressively load. An athlete does not begin with the maximum weight. A gymnast does not begin with the hardest skill. You give somebody difficulty at a scale they can survive, let reality push back, help them understand what happened, and then load a little more.

Over time they accumulate evidence about themselves. Discomfort ends. Embarrassment is survivable. Criticism can contain useful information. Preparation changes outcomes. Being wrong does not destroy you. Failure can be followed by another attempt.

This is what I mean when I tell my children that the hardest thing in life is managing your own psychology. Intelligence does not save you from fear. Talent does not save you from insecurity. Being right does not save you from ego. Knowing what you ought to do does not guarantee that you will do it.

A surprising amount of adulthood is remaining capable of acting while your own psychology is trying to convince you not to.

Which brings me to the message I worry about most, because it arrives sounding like sophistication.

Somewhere between the start of high school and the end of it, one of my children began telling me a story about his own future. Previous generations had taken the housing. Previous generations had taken the wages. The arithmetic of an ordinary adult life no longer worked, and there was not much point pretending otherwise.

I pushed back, and I want to be careful about what I was pushing back on. I was not arguing that housing is affordable or that the numbers are fine. Constraints are real, and a young person who cannot see them is not being educated, he is being flattered.

What I objected to was the shape of the conclusion. A structural fact had quietly become a personal verdict. He was not describing a difficult environment he would have to navigate. He was describing an outcome that had already been decided, which meant navigation was beside the point.

That is the mirror image of “follow your dreams,” and it fails for the same reason. One says the world will accommodate you. The other says the world will not permit you. Both remove the part where what you actually do makes a difference.

Narratives shape agency. Give young people tools, not verdicts.

The same idea applies to the people and environments we choose.

I have told my children for years that you cannot aspire to what you have not seen or experienced. We like to think our imagination is independent. It isn’t.

If you have never met anyone who built a company, building a company feels like something done by a different category of human being. Then you spend time around someone who has done it and the thing moves from abstract possibility into the set of things ordinary humans apparently do.

Spend time around engineers and engineering becomes concrete. Spend time around excellent tradespeople and craftsmanship becomes visible. See someone change careers later in life and reinvention becomes less frightening. Watch someone take a serious risk, fail, recover, and try again, and failure becomes less terminal.

This is part of what apprenticeship does extraordinarily well. The apprentice is not merely receiving instruction. The apprentice is watching what competent people consider normal.

And normal is contagious. So are standards. So are ambitions. So are fears.

Whether people like the implication or not, we become, in meaningful ways, like the people with whom we spend our time. Which is why I have come to think of the whole environment as three inputs worth choosing deliberately. People shape your standards. Problems shape your capabilities. Feedback shapes your calibration.

Those are decisions, and like any decision they are worth revisiting. I am not disciplined about this and I have stayed in lanes longer than I should have. But without some mechanism for reconsideration, inertia starts impersonating intention.

You do not need to predict your life. You do need to keep steering it.

All of this was already true before AI. AI makes one part of it harder to ignore.

Instruction is getting cheap and abundant. The judgment that used to accumulate as a byproduct of doing unimportant work is not. I have written about both of those elsewhere, the vanishing on-ramp and what turns scarce once reasoning is cheap, and will not argue them again here.

The piece that belongs in this essay is smaller and harder. Every one of those questions is a decision about what to do next, and there is no longer anyone obvious to hand it to. A model will tell you what is true. It will not decide what you are willing to own.

That does not require a new educational philosophy. It makes an old one newly relevant.

You need access. You need direction. You need problems that matter. You need people who know more than you do. You need enough consequence for reality to get a vote. And eventually you need responsibility for deciding what happens next.

Which brings me back to the thing Hurst University was actually built around.

Family.

When children are young, the family carries almost everything. Food, shelter, transportation, money, protection, opportunity, judgment, and most of the consequences of decisions all sit primarily with the parents.

Childhood is, in part, the gradual transfer of that weight. Not all at once. That would be abandonment. A little at a time, while mistakes are still cheap and there is somebody nearby who can help make sense of them.

At first we choose for them. Then we let them choose between things we have selected. Then they make decisions we would not have made. Then they live with some of the consequences. We advise more and decide less.

If the process works, responsibility moves almost imperceptibly from one side of the relationship to the other.

Eventually they leave the house. They do not leave the family.

That distinction is more important than I understood when I first started making the Hurst University joke. The goal was never independence in the sense of needing nobody. Families do not work that way, and neither does the rest of life. The goal was to change your position inside the family.

When you are small, the family carries you. For a long time that is its job. Then you begin carrying more of yourself. Your decisions become yours. Your mistakes become yours. Your work becomes yours. Your education becomes yours. Eventually the roof over your head becomes yours too.

And somewhere along the way, if things have gone well, another transition begins. You become capable of carrying some weight for the people who once carried all of yours.

That is much closer to what I mean by graduation.

Not that you know what you are going to do for the next forty years. Not that you have accumulated the correct credentials. Not that you have stopped needing your parents, your siblings, or anyone else.

You leave the house able to participate in the family as an adult. You can build enough of a life to carry yourself, and enough capability that when the people you love need something from you, you have something to give.

The graduate of Hurst University is not the person who has all the answers. It is the person who has become difficult to make helpless.

Thirty years ago I did not have all of this worked out. I had a joke about Hurst University and a conviction that my children needed to leave the house able to make a future for themselves.

I understand the joke a little better now.

The future was never the thing I could give them. The best I could do was help them become people capable of building one.

From Periodic Audit to Continuous Assurance

I have been writing about the limitations of audits and compliance systems for several years.

In Accountability and Transparency in Modern Systems, I wrote about systems producing evidence continuously rather than assembling it periodically for an auditor.

In First Principles for Root Store Management, I looked back at the decision to require WebTrust for publicly trusted CAs and argued that, if we were designing the system today, much more of the trust decision should be based on continuously verifiable behavior.

That led to The Limitations of Audits, Rethinking Compliance, and Compliance at the Speed of Code.

The common thread was that the systems we are trying to assure change much faster than the mechanisms we use to understand them.

Over the last year, I have spent considerably more time on this problem, both thinking about it and building systems intended to work differently. That work convinced me that the problem is deeper than periodicity alone.

I have pulled that thinking together into two new long-form pieces.

They are intended to be read together.

The first explains how we got here.

The second explores what comes next.

Steve Jobs, AI, and the Problem of Analysis Without Ownership

There is an old Steve Jobs clip from a 1992 MIT Sloan talk that feels newly relevant in the age of AI. In the talk, available here as Steve Jobs MIT 1992 Lecture, Jobs is asked about consultants. His answer is not that consultants are unintelligent or useless. His criticism is more subtle. He says consultants often get to see a lot, analyze a lot, and recommend a lot, but they do not stay with the work long enough to own the consequences.

They do not spend years living with the product, the team, the tradeoffs, the mistakes, the customers, the budgets, the bugs, or the recovery. They may see the fruit, as Jobs put it, but they “never really taste it.”

That distinction matters.

There is a kind of knowledge that comes from observation, and there is a different kind of knowledge that comes from ownership. Observation can make you articulate. Ownership makes you careful. Observation helps you describe what should happen. Ownership teaches you what actually happens when a recommendation meets constraints, incentives, politics, timelines, systems, and human behavior.

There is also a kind of knowledge that only comes from time.

Some problems cannot be understood in a single sitting. You need to carry them around for a while. You read, step away, come back, notice what still bothers you, test a different framing, sleep on it, and then see the thing that was hiding in plain sight. That kind of soaking is not inefficiency. It is often how judgment forms.

That is the parallel to AI.

AI is making analysis abundant. It can read more than we can read, summarize faster than we can summarize, find patterns across larger datasets, generate plausible options, and produce recommendations that sound polished and confident. That is useful. But it is not the same as judgment.

Used poorly, AI becomes consulting at machine scale. It is fast, articulate, and superficially impressive, but disconnected from whether its recommendations actually survive contact with reality.

It can say what should be done without knowing what happened after someone tried to do it. It can identify risks without understanding which ones mattered. It can produce a roadmap without living through the missed dependency, the customer objection, the policy constraint, the budget cut, the migration failure, or the second-order effect six months later.

It can also make us confuse speed of response with depth of understanding. That may be the deeper risk. AI can collapse the slow work of thinking into the first plausible answer. It can make a problem feel resolved before we have really spent time with it. It can produce fluency before we have earned conviction.

That does not make AI useless. It makes the design problem clearer.

The lazy version of the AI story is the self-driving car analogy, namely once the machine becomes safer, faster, or more consistent, the human gets pushed out of the loop. There will be domains where that is true. But much of knowledge work is different. The goal is not only to execute a task correctly. The goal is to understand the problem well enough to make better decisions the next time.

Execution tools can displace. Reasoning tools should compound.

That is why the most interesting promise of AI is not simply that it becomes a better consultant or even a better operator. It is that AI can help humans become better operators.

Used well, AI becomes a way to think with the material. It helps us understand datasets that are too large to hold in our heads. It lets us explore problem spaces from more angles. It helps test assumptions, compare interpretations, surface edge cases, and ask better questions. It can show us patterns we would have missed, but the value is not just the pattern. The value is that, through the process of interrogation, we understand the problem more deeply ourselves.

AI should not shorten our attention so much as deepen what our attention can hold.

A good AI system should help us return to a problem with more context than we had the last time. It should preserve the questions we asked, the assumptions we tested, the contradictions we found, the evidence that mattered, and the places where our understanding changed. It should make it easier to spend real time with the problem, not merely produce an answer faster.

In that sense, the best use of AI is not instant certainty. It is structured patience.

It lets us soak in a problem more effectively. By that I mean it enables us to hold more evidence in view, revisiting prior interpretations, comparing today’s answer to yesterday’s uncertainty, and gradually turning analysis into understanding.

The goal should not be to outsource judgment to AI. The goal should be to use AI to improve the conditions under which judgment is formed.

A good AI system should not merely say, “Here is the answer.” It should help us see why the answer might be true, where it might be fragile, what evidence supports it, what alternatives exist, and what would change our mind. It should help us move from diagnosis to action, from action to feedback, and from feedback to learning.

That is the line between AI as consultant and AI as learning partner.

This is also where many AI products will disappoint. Dashboards full of findings, risks, summaries, and recommendations can look impressive while still leaving the actual burden on the human team. They create the appearance of progress without necessarily improving understanding. The human still has to decide what matters, translate the finding into action, make the change, verify the outcome, and remember the lesson later.

The point is not that findings and recommendations are useless; they are necessary. Findings are the beginning of the loop, not the end of it. Systems that stop there are not doing judgment automation. They are doing analysis transfer.

The more interesting systems will close the loop. They will connect analysis to execution, execution to verification, and verification to institutional memory. Not because humans should be removed from the process, but because humans should be able to reason from a better substrate.

This is where Jobs’ point lands today. The scarce thing is not access to analysis. AI will make analysis abundant. The scarce thing is accumulated judgment, something that only comes from acting, observing, correcting, and learning over time.

Observation gives you language. Ownership gives you consequence. Time gives you depth. Feedback gives you judgment.

Jobs’ critique of consulting was not just a warning about consultants. It was a warning about any tool, process, or person that gets rewarded for sounding right without having to live with whether they were right.

AI will be most valuable not when it becomes the smartest consultant in the room, but when it helps teams build judgment faster, seeing more, acting sooner, sitting with the problem longer, verifying outcomes, and remembering what reality taught them.

The future of AI in knowledge work should not be analysis without ownership. It should be ownership made smarter.

The Prompt Is an Argument

The prior piece made a narrow claim. The prompt is the record, because a system can only act on what reaches it. Intent that stays in your head does not govern anything. Context that never reaches the model does not constrain anything. Purpose that is not in the prompt, the retrieved material, the tools, the policies, or the examples is not part of the decision environment.

If you accept that, the next question is unavoidable. What kind of record should a good prompt be?

For goal-oriented work, it should be an argument. More precisely, it should be enthymematic, an argument that leaves its obvious premise unstated for the audience to supply.

The form is Aristotle’s. He called the enthymeme the body of proof, the strongest of rhetorical proofs, a kind of syllogism with a premise left out. Its strength comes from the omission. Stating what the audience already accepts is tedious, while assuming the right premise makes the conclusion feel almost self-evident. That power holds on one condition. The missing premise has to be one the audience can already supply.

A capable model supplies a premise readily. It does not reliably supply yours, and from the output alone you cannot tell which one it used. Where your premise and its default mostly agree, the gap is cheap. Where the wrong one is costly, or where you have to reconstruct the reasoning later, it is not.

Look at a bad prompt with that in mind.

“Write about DevOps automation.”

That is a topic, not a goal. The model can go anywhere. CI/CD, infrastructure as code, job displacement, Kubernetes, a bland survey that explains nothing. It did not disobey. The prompt simply did not contain an argument for it to advance, so it advanced none.

Now the same subject with the premise restored.

“Explain why DevOps automation is becoming more viable now that production systems can be modeled, tested, and validated in synthetic environments.”

This carries a claim the first version left in your head. Automation gets safe where results can be checked. Coding agents became useful because code has feedback loops. It compiles or it does not, tests pass or fail, the type system objects. As production systems become modelable and testable, operations starts to acquire the same machinery, so it starts to look more automatable for the same reason coding did. You could not spell all of that out if you tried. The context behind any goal is unbounded, so every prompt is already a compression, and the only real choice is what to keep. Keep the load-bearing premise and drop what the model already handles. Here that premise is the causal claim, present enough that the model knows which answers would count as success, the one it would otherwise have to invent.

That is the difference between a task prompt and a goal prompt. A task prompt says do X. A goal prompt says do X in service of Y, because Z is the relationship that matters. The “because Z” is where most prompt failures live.

People leave it out because they assume the model already holds the frame. They write as if it knows the business context, the adversary, the institutional scar tissue, the product strategy, the audience, the risk appetite, the standard of correctness. Then a plausible, fluent, useless answer comes back and surprises them. The model was not confused. It was unconstrained. It got a task without the premise that made the task mean anything.

Humans skip premises constantly and get away with it. A lawyer says “that creates a reliance problem” and the room knows the shape of the issue. An engineer says “that breaks rollback” and the team feels the operational cost. A security person says “that moves the trust boundary” and the people who have lived with the system know why it matters. The shorthand works because the history is shared. A model does not inherit that history unless you hand it over. It does not know which premise is obvious inside your company, which analogy is carrying the real weight, which part of the request is decorative and which part is load-bearing. It does not know that “make this clearer” meant keep the technical claim but cut the wording that lets a reader hear monocausality.

This is why writing a good prompt feels more like drafting than asking. A good lawyer does not write words that merely sound like the client’s intent. A good lawyer writes words that survive interpretation by someone else, later, under pressure, with incentives to read them the wrong way. The document has to carry its operative meaning forward once the author has left the room. A prompt carries the same burden into a system that completes patterns from whatever materials it has. Leave the wrong premise implicit and the model may complete the argument in the wrong direction. Omit it and the model substitutes a generic one. Supply several competing premises and the model optimizes for the one easiest to write about rather than the one that matters. That is how a prompt produces fluent nonsense. Not that the model cannot write, but that the prompt did not preserve the reasoning.

So before writing a goal-oriented prompt, ask one question. What has to be true for this output to be useful? Not what topic it should cover, what format it should take, how long it should run. What has to be true. The answer is usually the missing premise. For a product strategy it is often the market wedge. For a security review it is the attacker’s actual path. For an executive summary it is the decision the executive has to make. For a critique it is the standard the work should be judged against. For a rewrite it is the misunderstanding you are trying to prevent.

That premise does not have to appear as a formal sentence. It can live in the framing, in an example, in the acceptance criteria, in the source material, or in an instruction about what not to optimize for. It only has to be somewhere in the record. Otherwise the system is not helping you pursue a goal. It is producing text near a topic.

In a single prompt you can hold the whole record in view. A production system spreads it out. The effective prompt is no longer the user’s sentence. It is that sentence plus the system instruction, the developer instruction, the retrieved documents, the available tools, the policies, the examples, the memory, the model version, and the configuration around all of it. The argument is distributed across those layers, which makes enthymematic design more important rather than less. The question stops being what the user asked and becomes what argument the system received. Did retrieval supply the missing premise or omit it? Did the tool definitions encode the right standard for action? Did the policy layer quietly override the user’s goal? Did the examples teach the wrong pattern?

Those are governance questions. A system that cannot reconstruct its effective prompt cannot reconstruct the argument it acted on. And a system that cannot reconstruct that argument cannot explain why its output was reasonable or unreasonable, compliant or not, safe or merely plausible.

The enthymeme works when the missing premise is shared enough to be supplied safely. That is the one condition these systems do not meet on their own.

So the work is not to make prompts longer. It is to make them carry the right inference.

The missing premise will be supplied either way. The only question is by whom. You provide it, or you let the system invent it.

A CA Built for the Threat Model We Actually Have

This builds on earlier posts on what attestation actually proves, what confidential computing is and isn’t, and an honest accounting of the problems with the current generation of TEEs. None of those problems go away here. The argument is that despite those limitations, attestation is an important tool. Certificate issuance is overdue to use it.

Back in the 1990s, I was doing some consulting for DigiNotar, yes, that DigiNotar. They had CA facilities in a data center whose perimeter still had WWII-era anti-tank obstacles, large concrete barriers sometimes called “dragon’s teeth.” Of course, this was an artifact of the facility’s history, but data centers are designed from a security perspective with layers of physical protection, including barriers, mantraps, biometrics, individual vaults with cages, individual racks with their own locks and biometrics, cameras, and more. The threat of physical theft, destruction, or manipulation is exactly what these facilities are designed to mitigate.

When building a CA inside one of these facilities, we design yet another layer of protection. Administration networks are segmented from transaction networks, interconnects from supporting infrastructure, the issuance environment from the systems holding root keys. We add our own physical segmentation on top of that so we can build controls around multiple parties being necessary for the more sensitive operations, while still letting routine hardware maintenance happen on the schedule the SLA needs.

These are all useful and important things, but the reality is that CA key material is not likely to be physically stolen. It is more likely to be compromised from the outside. We solve these problems through design, not by writing more code.

Meaningfully measured code forces design upstream of the code itself.

A measurement of a monolithic blob proves almost nothing useful. A measurement that names a specific role, a specific security domain, and a specific assertion the verifier is supposed to act on, proves something. The roles, the domain boundaries, and the questions the verification has to answer have to exist before any code is written, or the attestation is a signature on nothing in particular.

In operating system design, we have similar problems. In naive systems, we load cryptographic keys into memory on a running, network-connected system, accidentally exposing ourselves to memory-disclosure bugs where a network attacker can steal keys. Heartbleed is the canonical example, but the class is what matters. We do this because it is simpler and faster, but it is also less secure. As systems designers, we address this by moving those keys out of the process of the network-connected application and into a different user context. That way, an attacker cannot simply get the network-connected service to dump memory. They have to get persistence and cross a kernel-enforced user boundary.

This is old wisdom. Least privilege and privilege separation exist because network-facing code should not also be the thing that controls the keys.

A parallel showed up in early cryptocurrency exchanges. Hot wallets were used as signing oracles because the design and deployment work needed to prevent that had not been done, and many of the high-profile compromises of that era trace back to that gap. The exchanges that survived learned to put boundaries between the wallet and the network. That boundary did most of the work. The dragon’s teeth around the building did the rest.

When third parties need to rely on external services operating in these environments, they often rely on auditors to attest that management assertions about operational practices are actually being followed. These assessments are usually performed by CPAs, not security specialists, which can limit their value. They also often rely on sampling a small portion of transactions to confirm that the controls being evaluated are being followed. That sample is drawn from evidence provided by the entity being audited, which is also the party paying for the audit.

All of the things discussed above help bring some minimal level of transparency and verifiability, but it is turtles all the way down, layer on layer, none of them reaching the runtime where the actual compromise happens. This is where confidential computing, and solutions like Private Cloud Compute, start to matter.

Policy changes meaning in this model. In the traditional assurance world, policy is a written promise. The CA publishes a CP or CPS, the operator commits to following it, and the auditor samples evidence to decide whether that promise was kept. In a runtime-evidence model, policy becomes part of the mechanism. A measured binary evaluates a specific policy, produces a decision, and the digest of that policy travels with the evidence. The shift is from policy as promise to policy as enforcement, from “trust us, this is what we do” to “this is the policy the measured system actually applied.”

Apple’s Private Cloud Compute is the worked example. PCC nodes attest to the binary they are running, refuse to do work for clients that cannot verify that attestation, and publish every production build for public inspection. The user’s device, not Apple, decides whether a given node is acceptable. That inversion, the relying party verifying the service rather than the service asserting to the relying party, is the part of the pattern that matters. The pieces are not new individually. The combination, at the scale Apple shipped it, proves the pattern is real. The third-party security reviews prove the architecture is serious. Attacks on confidential computing do not refute that point. They prove there is now a boundary worth attacking, measuring, and improving.

Apple is not the only proof point. Signal used SGX remote attestation for private contact discovery in 2017, with clients verifying that the enclave was running the expected open-source code. WhatsApp’s end-to-end encrypted backups use an HSM-based Backup Key Vault to keep recovery keys out of the ordinary service path, and that design was publicly reviewed by NCC Group. Microsoft’s Confidential Consortium Framework powers Azure Confidential Ledger. Different systems, different threat models, same direction of travel. High-assurance services are moving from institutional assurances toward runtime evidence.

What it looks like

Concretely, a CA built on the Private Cloud Compute pattern looks like this.

Issuance is split into two attested components. The first, the registration authority, takes the certificate request, resolves identity from authoritative sources, evaluates the issuance policy, and produces a signed authorization context. The second, the signing oracle, holds the CA private key and produces the signature. Each runs in a separate attested enclave, and each is measured separately. This means policy can evolve without re-measuring the key-custody component, and keys can rotate without re-measuring the policy component.

The policy layer matters here too. Each component is not just running code, it is making a verifiable policy decision before it acts. The RA decides whether the request is authorized and the identity evidence is sufficient. The signing oracle decides whether the RA, the request, and the authorization context are acceptable before it signs. The evidence does not just say which binary ran. It also says which policy that binary evaluated.

The two components do not trust each other because they are on the same network. They trust each other through attestation, mutually verified at every connection, and the signing oracle does not merely accept the RA’s conclusion. Before it signs, it independently verifies the RA’s attestation, checks that the authorization context is fresh, confirms that the request is bound to an allowed profile, and verifies that the policy facts asserted by the RA match the evidence presented to the oracle. A compromised RA, even one with its own signing key, does not get to mint an out-of-profile certificate, bypass attestation, or turn the CA key into a general-purpose signing oracle.

The CA private key is not loaded by the operator. It is held by a custodian, a hardware security module, a cloud KMS, or another enclave, and it is wrapped so that the custodian will release it only to a signing oracle whose attestation matches a published image. The list of acceptable images is small, public, and updated through a documented process. An operator who runs a different binary, however benign the reason, does not get the key. The dragon’s teeth around the data center are still there. They no longer have to do the whole job.

Both the RA binary and the oracle binary are built from public source and are reproducibly buildable. Anyone can rebuild from the published sources, compare their measurement to the one in the attestation, and confirm that the two match. This is the part of the model that makes trust mean something specific. Not the operator’s word, not the auditor’s snapshot, not the CA’s policy statement, but the build process and the published source. To verify what a particular issuance was actually done by, you would not need to be admitted to the data center. You would need a compiler.

Each issued certificate is accompanied by a portable evidence bundle, signed by the attested issuance system. The bundle names the binary that produced the signature, the attestation root that vouched for the binary, the RA policy decision, the oracle policy decision, the identity assertion the RA accepted, and the inputs the oracle independently verified before signing. A relying party who trusts the chip vendor’s attestation root can determine for themselves whether the issuance was performed by code on the published list, against the policy on the published list, by an RA that accepted the identity claim it claimed to accept. The CA is not asked to be trusted. The CA is asked to produce evidence.

None of this removes the HSM, the auditor, or the operator. The HSM is still excellent at the threat it was built for, and a custodian holding a key wrapped to an attestation policy is still doing HSM work under the hood. The auditor is still needed to attest that the published policy is sensible, that the source matches the binary, that the threat model is honest, and that the runbook is followed in the moments where attestation cannot help. The operator is still needed to run the infrastructure and respond when things break.

What changes is what they are asked to prove.

Today, a relying party mostly gets institutional assurances. The CA says it followed its policy. The auditor samples evidence and says the controls were operating. The operator says the production system was the one described. Those are useful assurances, but they are indirect. They do not let the relying party inspect the actual path between a request, a policy decision, and a signature.

A Private Cloud Compute style CA changes that. It turns the issuance path itself into evidence. The question is no longer only whether the CA says it followed the rules. The question becomes which measured binary evaluated this request, which measured binary signed it, which policy digest was used, which identity evidence was accepted, what validation methods were used during issuance, and whether all of that matches the public commitment the CA made.

When the source is open and reproducibly buildable, that evidence includes a hash of the code that made the decision and signed attestations about the runtime elements that went into that decision. When the code is not open source, third parties can come in and validate the source, the build process, and the correctness of the claims, as Apple did with Private Cloud Compute. The public hashes then let others verify that the code claiming to provide these guarantees is, in fact, the code that ran.

Open source is not magic, and the point is not faith in “many eyes.” The point is that this shifts the emphasis from betting on physical security and operational practice audits to secure system design and cryptographic evidence about what code actually ran and what it actually did.

That is the threat model mismatch, and it is not only a CA problem. We built the WebPKI around buildings, cages, ceremonies, HSMs, and audits because those were the tools we had. We did the same thing cryptographically. We built systems around the assumption that factoring large composites and solving discrete logs on elliptic curves were out of reach. Q-day changes that assumption. Runtime compromise changes the operational assumption just as fundamentally.

We apply the same instincts in any environment we want to call high-assurance. They still matter, but most of the failures we care about are not physical failures. They are logical, remote, operational failures in the runtime path. The rate of change makes that gap wider every year. Annual audits are retrospective, and between them systems change thousands of times, so what the auditor described is rarely what is actually running when a relying party sees a certificate.

Cryptography turns security problems into key-management problems. AI turns assurance problems into runtime-evidence problems. Once agents are making decisions, calling tools, and changing state, the question is no longer what policy you wrote or what control an auditor sampled. The question is what actually ran, what it saw, what boundary contained it, what policy constrained it, and what evidence survived execution.

A Private Cloud Compute style CA gives us a way to make that path visible, attestable, and independently verifiable. The same pattern applies wherever the gap between what we say a system does and what it actually does at runtime matters.

The First AI-Built Zero-Day Is Not the Interesting Part

In the mid 90s I worked at a company called Cybersafe. Today it would get labeled an IAM/SSO vendor. What we actually built was a first-generation security platform: Kerberos, password management, PKI-based MFA, key management, host intrusion detection, and what would now be called zero trust access. The company failed for the usual startup reasons. People. Corporate Politics. Timing. The technology was a decade ahead of its market.

One debate from that period has stayed with me. As we expanded into host intrusion detection, the question of automated response kept surfacing. Could a system safely act on its own to contain an intrusion in progress? Drop a connection. Kill a process. Isolate a host. Nobody on the team could imagine a credible answer. The false positive risk was unbounded. The response itself could be weaponized. The rule sets were not trustworthy enough to delegate authority. We shipped detection and let humans make the call.

That debate has an answer now, and it is not the one we expected. Automation on the offensive side is not new. Worms, exploit kits, credential stuffing, and phishing infrastructure have been automated for decades. What is new is broad delegated judgment at machine speed, in the hands of people who do not have to worry about false positives because the blast radius is somebody else’s network.

What the report actually shows

The interesting question is not whether AI helped produce a zero-day. That was inevitable. The interesting questions are operational. What kinds of systems make bad machine judgment cheap enough to deploy at scale. What kinds of defensive systems are still pretending human review is the control boundary.

Google Threat Intelligence Group’s latest AI Threat Tracker report documents the first zero-day exploit that GTIG says it has high confidence was developed with AI assistance. The headline framing is technically correct. The specifics tell a more interesting story.

The exploit was a Python script that bypassed 2FA on an open-source web-based system administration tool. It required valid user credentials in the first place. The criminal group planned a mass exploitation campaign, and Google disrupted it through responsible disclosure to the vendor. GTIG identified the artifact as AI-developed because the code carried obvious tells. A hallucinated CVSS score. Textbook Python formatting. Detailed help menus. Educational docstrings characteristic of training data. The artifact still carried the seams of its production.

This is not the LLM failing at the hard part. The vulnerability itself is a real find. GTIG specifically notes that the 2FA flaw stems from a hardcoded trust assumption, a high-level semantic logic flaw of the kind that fuzzers and static analyzers tend to miss but that frontier LLMs can reason about by reading developer intent. The model did discovery work that previously required a competent human auditor. Where the operation broke down was in weaponization. The attacker shipped an artifact that still looked like a tutorial.

This is a familiar failure pattern showing up on the offensive side for the first time. Fluency reads as competence. The attacker trusted an artifact with hallucinated metadata and educational comments still attached because it looked like a real exploit, in the same way over-eager engineering teams hand agents production credentials because the agent sounded like it knew what it was doing. The criminals here got bitten by the same dynamic that has been producing outages and data loss in vibe-coded production systems for the last eighteen months. The substrate is doing some of the work of inviting the misconfiguration.

Hultquist’s thread on the report is hedged correctly. The importance is the trajectory, not this specific specimen. Pull the camera back and the rest of the report is more interesting than the lede.

Three things worth surfacing

APT45 sending thousands of repetitive prompts. The North Korean group has been observed using recursive prompting to analyze CVEs and validate proof-of-concept exploits at scale. That is the industrial-scale answer to LLM variance. Solve the quality problem by amortizing across volume, then have humans cherry-pick the outputs that survived validation. The same statistical strategy that makes modern fuzzing work, applied one layer up the stack. The model does not have to be reliable. The pipeline has to be cheap enough that unreliability does not matter.

CANFAIL and LONGSTREAM using LLM-generated decoy code. A Russia-nexus intrusion cluster has been deploying malware that uses LLM-generated code to conceal malicious functionality. GTIG documented LONGSTREAM containing 32 instances of code querying the system’s daylight saving status, repetitive benign-looking activity used to camouflage the malicious core. CANFAIL carries similar filler logic with LLM-generated comments self-describing the decoy blocks. The stylistic noise of LLM output is becoming the obfuscation layer. The verbose docstrings. The textbook structure. The over-explained variable names. These used to be tells. They are now camouflage. Any heuristic built on the AI-tell will start producing false negatives.

The wooyun-legacy skill plugin. A specialized GitHub repository is being distributed as a Claude code skill plugin that integrates a distilled knowledge base of over 85,000 real-world vulnerability cases from the Chinese bug bounty platform WooYun (2010 to 2016). This is the supply side of the same market. Skill packs are tooling. Tooling gets distributed. The economic logic for adversarial skill packs is identical to the economic logic for legitimate ones. Any platform hosting them inherits a familiar problem. App stores and package registries have been working through it for two decades. Making trust decisions at distribution scale about code from parties you cannot directly inspect.

Both sides are running on the same substrate

On the defensive side, Google is using Big Sleep to find vulnerabilities and CodeMender (Gemini-driven) to fix them automatically. The criminals are pulling from a model class indistinguishable from the one Google is running its defensive tooling on. Both sides have access to the same substrate. The differential collapses to data quality, harness sophistication, and discipline around permissions.

That last one is the part the 90s HIDS conversation did not anticipate. It is also the part that should be the least surprising. The controls discipline did not get easier because the platform got more capable. If anything the gradient got worse. A confused regex IDS in 1999 had a bounded action space. The rule set was enumerable. You could write down what it would do wrong. A confused agent in 2026 has whatever action space its credentials grant it, which in most deployments is more than it should. The fluency that made it easy to give the agent broad permissions in the first place is exactly the property that makes its failures look reasonable in the moment.

The race Hultquist refers to is real, and it has started. The race is not about model capability. Both sides are running models from the same vendors, often the same model. The race is about who has better-curated data feeding their harnesses. Who has stricter discipline around what their automation can touch. Who has the institutional memory of what happens when you delegate authority to a system whose judgment you cannot audit in advance.

The HIDS debate from the mid-90s got an answer. It came from the other side of the wire. Not because defenders learned how to trust autonomous judgment, but because attackers learned they did not need to. They could delegate broadly, externalize the blast radius, and let volume compensate for judgment. The defensive answer cannot be more vibes, broader credentials, and better prompts. It has to be the inverse. Narrower authority. Better harnesses. Replayable decisions. And institutional memory about what happens when fluent systems get mistaken for trustworthy ones.

Smaller, Provable, and on Hardware You Own and Operate

Dino Dai Zovi made an argument recently that I want to build on.

“If you agree that AI will help attackers discover and exploit vulnerabilities 10-100x more easily, then your excess attack surface has also just become 10-100x more of a liability. The right defensive strategy is to prioritize reducing attack surface and trusted computing bases.”

The argument is right. It is also not new.

We have been working on this problem for fifty years

Operating system designers gave this set of principles a name in 1975. Saltzer and Schroeder published The Protection of Information in Computer Systems and laid out economy of mechanism, least privilege, separation of privilege, complete mediation, fail-safe defaults, and open design. The Orange Book formalized “trusted computing base” a few years later, with the central observation that the security of a system depends on what is inside the TCB, and that smaller TCBs are easier to make trustworthy than stronger ones. The microkernel debate that ran from Mach through L4 was an argument about how aggressively to apply these principles to commodity systems. seL4 went further and produced a formally verified microkernel in 2009, demonstrating that the principles could be pushed all the way to mathematical proof.

The same ideas show up everywhere once you look. Chrome’s site isolation is privilege separation applied to the browser. OpenBSD pledge and unveil are least privilege applied to userland. Linux namespaces, capabilities, and seccomp are mediation primitives. CHERI takes the same intuitions down into the instruction set. GlobalPlatform Security Domains are the smart-card-world version of compartmentalized trust, with separate keysets, separate trust roots, and isolation between issuers, verifiers, and applications on the same chip.

None of this is new vocabulary. Security domains. Privilege separation. Attack surface reduction. Trusted computing bases. We have known the names of these things for decades, and we have known what to do about them.

What AI changes is the math, not the principles. Excess privilege has always been a liability. The probability of it mattering on any given day was low enough, and the timescale on which it mattered was long enough, that organizations could carry oversized TCBs and broad blast radii in the backlog as “things we should clean up someday.” AI compresses the timescale and raises the probability. The slack that was tolerable on a five-year cleanup horizon is not tolerable on a six-month one. Dai Zovi’s 10-100x is a multiplier on the cost of carrying slack, not a discovery about whether slack should be carried.

The OS tradition assumed you owned the layer below the boundary

There is one place where the classical OS framework needs an extension before it covers the world we are actually deploying into.

The kernel could enforce process isolation because the kernel was below the processes. The hypervisor could enforce VM isolation because the hypervisor was below the VMs. The trust property was “I control the layer below the boundary, so the boundary is meaningful to me.” Every classical OS-level guarantee depends on that.

Cloud broke that assumption. AI workloads, which run on cloud GPUs and orchestration infrastructure that almost nobody owns, intensify the break. The layer below your workload is operated by someone else. Their hypervisor, their firmware, their physical facility, their scheduling. The classical principles still apply, but their enforcement mechanism is gone.

Reduction is necessary. Reduction is not sufficient. Once you have shrunk the attack surface and the TCB to something defensible, you still have to prove that the small thing you reduced to is the small thing actually running, and that what it just did is what you said it would do. Without that proof, the small thing is functionally indistinguishable from the large thing. An attacker who replaces your tiny attested signing service with a tiny lookalike has bought themselves all the same access at a lower cost.

The defensive posture in an AI-leverage world is not just smaller. It is smaller and provable.

Law #3 did not go away

There is also one law older than the OS-design principles that the cloud security pitch of the last decade has spent a lot of energy pretending to repeal.

Microsoft’s Ten Immutable Laws of Security were published by Scott Culp in 2000. Law #3 is the relevant one here. If a bad actor has unrestricted physical access to your computer, it’s not your computer anymore. The marketing for confidential computing has, in effect, been an extended argument that hardware-encrypted memory and remote attestation make Law #3 obsolete on cloud infrastructure. They do not, and the research record is clear that they will not.

Cloud TEEs share microarchitectural resources with the hypervisor and with co-tenants. That is what produces the side-channel catalog. Cloud providers have physical access to every server they operate. That is what produced TEE.Fail. Hardware roots of trust have a shelf life because they live on the same silicon as everything else, and that silicon is in the operator’s possession. None of these properties are bugs. They are what “running on hardware somebody else owns” means.

Server-side cloud TEEs are useful for narrow, bounded properties. They are not useful for repealing Law #3 against a determined operator, and they will not meaningfully defeat multi-tenant side channels at the scale at which they are deployed. Selling them as if they would is what produces the gap between marketing and engineering that I have been writing about for the last year in Confidential Computing’s Inconvenient Truth, What Is Confidential Computing, What It Isn’t, and How to Think About It, and TPMs, TEEs, and Everything In Between.

The criticism in those pieces is specific. It is about the gap between what cloud TEEs are sold as doing (defeating the operator) and what they actually do (making narrow verifiable claims to relying parties about specific operations). The criticism is not that the underlying assurance technology is useless. The technology delivers exactly what it was originally designed to deliver, in the contexts where the original threat model holds. The marketing has been run over those contexts.

Where the assurance property actually delivers

The assurance property does deliver, where the model fits. The model fits when the hardware is in the user’s possession, when the device is discrete and tamper-resistant, and when attestation is used to prove “the key in this request lives on this specific device and has never left it” rather than to prove “the operator of the rack cannot read your memory.” That is the threat model the technology was designed for, and it has been working in production for a long time.

A few examples of the pattern done honestly.

YubiKey PIV attestation. The YubiKey can produce an attestation certificate, signed by Yubico’s manufacturer key, asserting that a private key was generated on this YubiKey, has the slot and policy attributes you expect, and is non-exportable. Yubico documents the protocol clearly. The trust property is sharp because the device is sharp. Discrete silicon, tamper-resistant package, manufacturer chain you can pin against. Law #3 still applies, and it cuts the right way: the user has unrestricted physical access to the YubiKey, and the YubiKey is the user’s computer.

Apple Secure Enclave for SSH agents. Paprika and Secretive are SSH agents that store the private key in the Mac’s Secure Enclave Processor. The application processor never sees the key, and even root on the Mac cannot extract the key material. Root can still cause the key to be used through the legitimate signing API, modulo whatever consent prompts apply, but extraction itself is what the SEP boundary is built to defeat. The user owns the laptop, the key is on a physically separated processor on the same SoC, and the threat model (other applications on the same device, or malware that compromises the application processor) matches what the SEP was built for.

Smart cards and HSMs. GlobalPlatform Security Domains, the Yubico PIV applet, hardware-backed PKCS#11 tokens, FIPS 140-3 Level 3 modules. Discrete silicon, tamper-resistant packaging, attestation chains rooted in manufacturer keys. The model that worked in the late 1990s and that still works today, because the threat model has not drifted.

PeculiarVentures/attestation is the verification side of all of this. Parsing, validating, and reasoning about attestation evidence from these various sources. Attestation without a verifier is a claim. Attestation with a verifier is something the relying party can act on.

The common shape across all of these is that the user owns the hardware, the boundary is physical, and the attestation chain anchors in a manufacturer key whose threat model the user can actually evaluate. Law #3 is honored rather than denied.

Transparency is the other cross-machine extension

There is a second extension of the classical OS-design tradition that matters for the AI-leverage world, and that composes with attestation in important ways.

Saltzer and Schroeder’s open design principle says the security of a system should not depend on the secrecy of its mechanism. The cryptography community has applied this rule to algorithms for decades. The systems community has been slower to apply it to operations. What is the rack actually doing right now? and what has it done in the past? are operational questions, and historically the answer was “trust the operator’s audit logs.”

Transparency logs are the operational extension of open design. The idea is to publish what a system is doing to an append-only public log, with cryptographic proofs that the log cannot be retroactively modified, and to design the relying party to require evidence from the log before trusting any operation. Multiple independent witnesses cosign the log so that no single party can serve different views of reality to different relying parties.

The pattern is in production at scale. Certificate Transparency requires every WebPKI certificate to be logged publicly before browsers will trust it, which converts CA misissuance from “discovered by accident, sometimes” into “discovered by anyone watching the log.” Sigstore applies the same model to software signing, with every signature published to Rekor and consumers able to require log inclusion before accepting a binary. Google DeepMind’s Verifiable Data Audit was an early attempt to apply the same model to data access in healthcare. The infrastructure is consolidating at transparency.dev, and C2SP standardizes the interoperability primitives: tlog-tiles, the witness and cosignature protocols, signed-note, and static-ct-api.

Attestation tells a relying party “this code is running right now.” Transparency tells a relying party “this code has been published, reproduced, and witnessed by parties whose collusion would be visible.” The two compose. Apple’s Private Cloud Compute is the most prominent recent example. Every production build is published to a transparency log, user devices will only communicate with nodes whose attested measurement matches the log, and Apple released a virtual research environment so anyone can verify the build claims independently. Google’s Project Oak was an earlier expression of the same combination, building remote attestation against publicly-published binaries as the foundation of trust. The Merkle Tree Certificates draft, now a working group document in the IETF’s new PLANTS working group, extends the same logic to TLS at scale, replacing traditional X.509 issuance with batched, transparency-native cert formats designed for the shorter lifetimes the WebPKI is moving toward.

The relevant property for the AI conversation is that transparency reduces the number of parties you have to trust to one less than would otherwise be required. With attestation alone, you trust the manufacturer of the silicon. With transparency, you trust any of the witnesses to be honest, plus the manufacturer of the silicon. That asymmetry is what makes transparency the right tool for environments where the operator might be the adversary.

What this leaves for server-side TEEs

Bounded usefulness, designed honestly.

Server-side cloud TEEs do not defeat the operator. They produce narrow verifiable claims that a relying party can check against their own trust anchors. This signing service ran this image at this measurement. This certificate was produced by this enclave for this RA. This policy was applied. This key was attested as non-exportable by the HSM that signed. Each of those is a useful property. None of them is “the operator cannot see your data.” Building an architecture that pretends otherwise is how organizations end up with a single point of failure they did not know they had.

I have been building GoodKey CA as a worked example of the bounded-usefulness pattern. A certificate authority is a useful test case for this kind of architecture, because the trust property is sharp and the threat model is well understood. The shape of the answer is mostly classical OS design pulled across machine boundaries, with hardware-anchored trust at the endpoints and a deliberately bounded intermediary in the middle.

Each enclave is a security domain. RA, CA, and HSM are independent compartments. Each has its own measured image, its own keys, and its own attested boundary. Compromising one does not compromise the others. Privilege is separated by design rather than by policy.

The TCB inside each domain is small enough to characterize. Each enclave runs a single-purpose deterministic image. The measurement is one number. The image is reproducible from source. There is no general-purpose runtime to subvert and no orchestration sidecar to gain a foothold from. AWS Nitro Enclaves were the deliberate choice over SGX or TDX. The architecture uses VM-level isolation with dedicated CPU and memory rather than carving enclaves out of shared-cache, shared-core silicon, which reduces a large class of the microarchitectural side-channel exposure that the SGX and TDX families have to grapple with. Dedicated resources, minimal hypervisor, deterministic measurement.

Mediation is complete and inside the boundary. Every signing operation goes through the policy evaluator (Cedar) inside the enclave. Authorization is part of what is attested, not external to it. A compromised RA cannot lie about what policy was applied, because the policy evaluation was inside the measurement.

Trust is not transitive. When the RA tells the CA that a client attestation passed, the CA does not believe it. The CA re-runs the verification itself, against its own registered verifier, before signing anything. This is the cross-machine version of “the kernel does not trust userland’s claim that a syscall is authorized.” The CA does the check itself, every time.

Per-operation attestation, not per-boot attestation. The CA produces a fresh Nitro attestation for every certificate it signs, with user_data set to SHA-256(certDER || raKeyFingerprint). That binds this specific certificate to this specific enclave with this specific RA on the other end of the conversation. A boot-time attestation tells you the box looked right when it started. A per-operation attestation tells you the box looked right when it did the thing you actually care about.

Hardware-anchored trust at the endpoints. The signing keys themselves live in a hardware HSM with discrete-silicon attestation rooted in the Marvell manufacturer chain. The clients prove they hold hardware-protected keys via TPM or device attestation. The Nitro layer in the middle does not have to defeat AWS to be useful, because the actual key material is protected by a different boundary that AWS does not own, and the evidence on the wire is anchored in trust roots the relying party already trusts.

Operations published to a transparency log. The CA’s attested measurements, policy versions, and issuance records get logged to an append-only structure with multi-witness cosigning. The operator still chooses what to submit. What the operator does not get is the ability to retract entries after the fact, modify history, or serve a different version of the log to a different relying party without those parties detecting the divergence. A relying party’s confidence that the system has been running honestly over time stops being a function of trust in the operator’s audit logs and starts being a function of properties that hold against the operator. This is the same shape Certificate Transparency gives the WebPKI, applied to the CA’s own operational claims about itself.

Failure modes are bounded by design. Certificates are seven days. ACME Renewal Information lets the CA shorten renewal windows targeted at specific machines or specific profiles, and goodenroll polls for those signals on its own schedule. The fleet rotates without an emergency window and without anyone touching a machine. The exposure window becomes a configuration choice rather than a function of certificate lifetime, and revocation infrastructure stays out of the critical path of the threat model.

Post-quantum where it counts. ML-DSA-65 (FIPS 204) for certificate signing, ML-KEM-768 (FIPS 203) as the subject key for TLS key-exchange certificates. ARI is what makes the migration tractable on the deployed fleet, because you do not have to wait for natural expiry to do the work.

Nitro is a bounded-trust intermediary. AWS still owns the silicon it runs on. What the architecture buys you is that the property the relying party has to verify is narrow and concrete, and that the actual long-lived secrets are protected by hardware that AWS does not own. Against an AWS-internal threat with full physical access and unbounded effort, Law #3 still applies. Against the attacks the architecture is actually defending against (software compromise of the CA pipeline, a rogue admin pulling secrets through the management plane, a tampered build reaching production), the bounded property is exactly the property you need.

The substrate

An architecture like this only works if the underlying primitives are right. Three pieces of infrastructure I have been spending time on are upstream of GoodKey CA.

PeculiarVentures/scp is GlobalPlatform Security Domain key management in Go. The name is not a coincidence. Smart cards and HSMs have been doing security domains in hardware for two decades, with separate keysets, separate trust roots, and isolation between issuer, verifier, and application code on the same chip. The library implements SCP03 and SCP11 and a typed Security Domain management layer for key lifecycle, certificate provisioning, and trust validation, against verified profiles with byte-exact validation against independent reference implementations. This is the unglamorous work of “make sure the keys you are putting on hardware are actually being put on hardware in the way you think they are.” If the key on the device is not where you think it is, every downstream signature is asserting something false.

draft-ietf-acme-device-attest, which I am a co-author on, is the cross-machine extension on the client side. It standardizes how a device proves to an ACME server that the key in a certificate request lives in attested hardware on a specific device. The recent revisions resolved several interoperability gaps that had blocked broad implementation, including the Apple-specific attToBeSigned semantics around sha256(token) versus sha256(keyAuth), an explicit identifier-verification step, the badAttestationStatement error type, and a hardware-module identifier type. The point of the work is to make the client side of the trust chain as verifiable as the CA side. An attested signing service that issues credentials to anyone who asks is not solving the problem, it is moving it.

PeculiarVentures/attestation closes the loop. It is the verifier side that consumes attestation evidence from these various sources (TPMs, YubiKeys, Apple devices, Nitro Enclaves) and reduces it to claims a relying party can act on. Without a verifier, attestation is marketing. With a verifier, it is engineering.

These are not separate efforts. They are what makes hardware-anchored cross-machine trust mean anything in the wild. The transparency-log side of the same problem is being standardized in parallel through transparency.dev, C2SP, and the Merkle Tree Certificates draft, which together extend the same model to issuance auditability at WebPKI scale.

What this asks builders to do

The Dai Zovi prescription is operating-systems hygiene applied to the whole stack. The verifiability corollary is the same hygiene extended across machines you do not own. Both are old. AI is what is making them mandatory.

Pick small. Compartmentalize. Strip privilege to what each component genuinely needs. Make each component’s TCB small enough that one person can characterize it in a sitting. Single-purpose services, deterministic builds, dedicated resources rather than shared microarchitectural state, single-image enclaves rather than orchestrated runtimes.

Make it provable across machines. Per-operation attestation rather than per-boot. Independent re-verification at every hop, not transitive trust. Authorization decisions inside the attested boundary. Evidence bundles the relying party can run a verifier against, with their own trust anchors. Short lifetimes with active rotation rather than long-lived credentials backstopped by revocation. And publish the operations themselves to a transparency log with independent witnesses, so the proofs survive disagreement about who saw what when, and so a single dishonest operator cannot serve different versions of reality to different relying parties.

Anchor trust in hardware whose threat model you can actually evaluate. Where you can put the long-lived secret on hardware the user owns, do that. YubiKey, Apple Secure Enclave, TPM in the laptop on the engineer’s desk, smart card in the operator’s pocket. Where you cannot, use a cloud TEE as a bounded-trust intermediary that produces narrow verifiable claims, and design the architecture so the long-lived material lives in a different boundary that the cloud operator does not own.

And know what your assurance is buying you. Cloud TEEs are not how you defeat the operator. They are how you make narrow operations verifiable to relying parties while accepting that absolute properties against the operator are not on offer. The places where attestation delivers what it advertises are the places where the user owns the silicon. Law #3 has not been repealed, and AI has only raised the cost of pretending otherwise.

Smaller is the easy half. Provable is most of the engineering. On hardware you own is where the property actually holds.

The Illusion of Constant Acceleration

Spend enough time around AI right now and you start to get the feeling that everything is speeding up, all the time.

Every week there is a new model, a new capability, a new claim that some industry is about to be remade. It starts to feel like rapid change is just the new baseline. Like history has bent into a permanently steeper slope.

I do not think that is right.

What I think is closer to the truth is that we have gotten used to confusing motion with progress, and delay with inevitability. Some things are moving very quickly. Others are barely moving at all. We treat the former as inevitable and the latter as unavoidable.

Neither is true.

My father was born in 1942. That is not ancient history. When he was born, there was still a lot of basic infrastructure left to build.

Within a little more than a decade, nonstop transcontinental passenger air service became viable. Less than eight years after that, a human entered space. Eight years later, people were walking on the Moon.

That is a staggering amount of change in a very short period of time.

In one person’s early life, we went from making coast-to-coast air travel practical to landing human beings on another celestial body. Not as a thought experiment. Not as a roadmap. We just did it.

And it was not only aerospace. The Golden Gate Bridge was built in about four years. The first transcontinental railroad was completed in about six. These were massive physical undertakings that reshaped how people moved and how economies functioned, delivered on timelines that would feel almost implausible now.

The easy way to dismiss this is to say that software is fast and physical infrastructure is slow. That if AI looks fast and transit looks slow, that is just how the world works.

But that does not really hold up.

Ukraine did not build its drone ecosystem on leisurely timelines. Tesla compressed what many assumed would be a slow industrial transition into something the rest of the auto industry had to react to. When something actually matters, physical systems move. Supply chains get reorganized. Tradeoffs get made. Bureaucracies get bent. Talent concentrates. People stop explaining why something is hard and start figuring out how to get it done.

That is part of what makes Artemis interesting.

This is not a criticism of Artemis. It is an ambitious and serious effort. But it is also a reminder that progress is not self-sustaining. Apollo is often remembered as a triumph of technology, but it was just as much a triumph of focus, alignment, and urgency. Artemis reminds us that those things matter just as much as the rockets do.

There is another force that shows up in systems like this.

At Google, there was a name for it: slime mold.

It is what happens when layers of process, approvals, coordination costs, and local incentives build up over time until forward motion gets harder even when nobody involved is being unreasonable. Everything makes sense on its own. The system just moves more slowly.

Technology policy has its own versions of slime mold.

We saw it in the crypto wars, when policymakers convinced themselves that math could be slowed down with policy, as if cryptographic reality were open to negotiation. It was not. What that produced was not real control. It produced friction, workarounds, and the illusion of governance.

You can see the same instinct showing up again in parts of the conversation around AI. When institutions feel outpaced, they respond with process. That instinct is understandable, but it rarely solves the problem. You do not make systems safer by pretending inevitabilities are optional. You make them safer by building the infrastructure, incentives, and accountability needed to deal with what is actually happening.

But that is not how we tend to think about progress.

We talk about technological achievement as if it were mostly about invention, as if once something has been demonstrated it remains latent in society, ready to be called back into service whenever we need it.

That is not how any of this works.

The ability to do ambitious things quickly depends on organizational memory, industrial capacity, political alignment, tolerance for risk, and a culture that still expects big things to happen on human timescales.

Lose enough of that, and even getting back to where you once were becomes hard.

You can see it in infrastructure. Projects that once would have been treated as urgent now take decades, often in fragments so small that earlier generations would have treated them as preliminary milestones. Over time, that changes expectations. Slowness starts to look like responsibility. Ambition starts to sound naive.

That is the trap.

The problem is not just that progress slows. It is that people get used to it. What would once have looked like drift starts to look like process. What would once have sounded like an excuse starts to sound like maturity.

Meanwhile, in domains where urgency and incentives line up, things still move very quickly. ChatGPT was released publicly in late 2022. In a few years, AI went from something most people associated with research labs to something embedded in everyday workflows, products, and policy debates.

AI did not prove that everything is accelerating.

It proved that when enough capability, capital, and attention line up, rapid change is still possible.

That is the point.

The world is not uniformly speeding up. Some parts of it are. Others are not. And the difference has less to do with atoms versus bits than with whether we have decided something actually matters.

That ought to make us a little less complacent.

People like to tell themselves that once a technology is important enough, the rest somehow sorts itself out. The problems get solved. The risks get managed. The surrounding systems catch up.

History does not really support that.

Things were only all right in the past because people worked very hard to make them all right. The systems that made aviation safe, that made infrastructure dependable, that made computing usable in high-trust environments, none of that appeared on its own.

The same will be true here.

If we want AI to be safe, trustworthy, and broadly useful, that will not happen as a side effect of capability gains. Security will not emerge on its own. Governance will not emerge on its own. The infrastructure needed to make these systems worthy of dependence will not emerge on its own.

Those things only happen when people decide they matter.

That is the real problem with the idea that everything is accelerating. It makes it easy to believe that progress takes care of itself.

It does not.

Progress happens when people decide it needs to, and then do the work.

Confidential Computing’s Inconvenient Truth

This is part of a series on confidential computing. See also: Confidential Computing: What It Is, What It Isn’t, and How to Think About It for practical deployment guidance, and Why Nobody Can Verify What Booted Your Server for the attestation infrastructure gap. Two companion reference documents provide the evidence base: the TEE Vulnerability Taxonomy and TPM Attestation and PCR Verification: The Infrastructure Gap.

Confidential computing has a vulnerability record that grows every year, an attestation infrastructure that does not work at scale, and a hardware root of trust with a demonstrated shelf life. This piece explains why.

I want to be clear about where I stand before cataloging problems. I believe in this technology. What Signal has done with Private Contact Discovery and Sealed Sender using SGX enclaves, building systems where even Signal’s own servers cannot see who is contacting whom, is exactly the kind of architecture that confidential computing makes possible. Apple’s Private Cloud Compute takes the model further. Every production build is published to a transparency log, user devices will only communicate with nodes whose attested measurements match the log, and Apple released a virtual research environment so anyone can verify the claims independently. Moxie Marlinspike’s Confer applies the same idea to AI inference, with all processing inside a TEE and remote attestation so the service provider never has access to your conversations. These are real systems delivering real privacy guarantees that would be hard to achieve any other way.

More broadly, TEEs make systems more verifiable. Instead of asking users to take on faith that a service handles their data correctly, the service can prove it through attestation. I wrote earlier about attestation as the MFA for machines and workloads, and I explored the same idea in 2022 in the context of certificate authorities. If the CA runs open-source software on attesting hardware with reproducible builds, you can verify its behavior rather than trusting an annual audit. That shift, from asserted trust to verifiable trust, is genuinely important, and confidential computing is what makes it possible.

But “the direction is right” is not the same as “the current state is adequate.” We should not make perfection the enemy of good. This technology delivers real value today. But we also cannot afford to mistake the current state for the desired end state. Getting to where this technology needs to be requires seeing clearly where it actually is. That is what this piece is about.

The answer is not “the implementations are buggy.” The answer is structural. These technologies were designed for threat models that do not match how they are being deployed. Smart cards and HSMs were physically discrete devices with clear trust boundaries. TPMs were designed for boot integrity on enterprise desktops. Intel SGX was designed for desktop DRM. Each was repurposed for the cloud because the technology existed and the market needed something now. The repurposing created systematic security gaps that the research community has spent a decade documenting and the market has spent a decade deploying through.

In March 2025, I published a technical reference on security hardware and an in-depth companion document that categorized how these technologies fail. One of those failure categories was “Misuse Issues”: vulnerabilities that occur when security technology is adopted beyond its original design. A year later, with TDXRay reconstructing LLM prompts from inside encrypted VMs, TEE.Fail extracting attestation keys with a $1,000 device, and the SGX Global Wrapping Key extracted from hardware fuses, that observation warrants a much fuller treatment.

Timeline

YearEventCategory
1968Smart card patents (Dethloff, Moreno). Special-purpose computers in tamper-resistant packages. The original TEE.Hardware TEE
1980sIBM secure coprocessors for banking. US government funds kernelized secure OS research.Hardware TEE
1996nCipher founded. nShield HSMs with CodeSafe: custom application code inside tamper-resistant hardware.Hardware TEE
1998IBM 4758 commercially available. Arbitrary code execution inside tamper-responding enclosure. FIPS 140-1 Level 4.Hardware TEE
2003TCG founded, TPM standardized. Designed for boot integrity from ring -x. Hardware root of trust, measurement chains, attestation concepts established.Institutional
2006AWS launches EC2. Public cloud computing begins. Workloads move to shared infrastructure owned by someone else.Cloud
2006BitLocker ships with TPM support. TPMs reach millions of enterprise devices. Reference value infrastructure never materializes.Hardware TEE
2008-2010Cloud goes mainstream. Azure (2010), GCP (2008), OpenStack (2010). Multi-tenant shared infrastructure becomes the default enterprise compute model.Cloud
2012AlexNet wins ImageNet. Deep learning proven at scale on GPUs. AI workloads begin moving to cloud GPU infrastructure.AI
2013Apple Secure Enclave Processor (iPhone 5s). Physically separate processor on SoC. First mass-market TEE. Invisible to users.Hardware TEE
2015Intel SGX (Skylake). Enclaves inside the CPU. Designed for desktop DRM: single-tenant threat model. Cloud providers begin evaluating for multi-tenant use.CPU TEE
2016AMD SEV. VM-level memory encryption. First CPU TEE designed with virtualization in mind.CPU TEE
2017Transformer architecture published (“Attention Is All You Need”). Foundation for the model scale that will drive confidential computing demand.AI
2017First SGX side-channel attacks. Cache-timing, Spectre adaptation. Desktop design meets multi-tenant reality.Vulnerability
2018Foreshadow (L1TF) reads arbitrary SGX memory. SEVered remaps SEV guest pages. Desktop-to-cloud threat model gap exploited.Vulnerability
2019Confidential Computing Consortium founded (Google, Microsoft, IBM, Intel, Linux Foundation). Repurposing becomes official strategy.Institutional
2019Plundervolt, ZombieLoad, RIDL. Three distinct attack classes against SGX in one year.Vulnerability
2020GPT-3 (175B parameters). Model weights become billion-dollar assets. Protecting weights on shared infrastructure becomes a business requirement.AI
2020AWS Nitro Enclaves. Purpose-built for cloud, not repurposed from desktop. The exception to the pattern.Cloud
2020AMD SEV-SNP, Intel TDX announced. VM-level TEEs designed for cloud but still sharing microarchitectural resources. Azure/GCP ship confidential VMs with vTPMs.Cloud
2021Intel deprecates SGX on consumer CPUs (11th/12th gen Core). Desktop DRM cannot sustain the technology alone.CPU TEE
2022ChatGPT launches (Nov). AI goes mainstream. Every enterprise begins evaluating LLM deployment on cloud infrastructure.AI
2022ÆPIC Leak, SGX.Fail. Vulnerable platforms remain in TRUSTED attestation state months after disclosure.Vulnerability
2023GPT-4, Llama 2, Claude 2. Foundation model race accelerates. EU AI Act passed.AI
2023Downfall (SGX), CacheWarp (SEV-SNP). CacheWarp is first software-based attack defeating SEV-SNP integrity. NVIDIA H100 confidential GPU ships.Vulnerability
2024Confidential AI goes mainstream. Azure, GCP, AWS all position confidential computing for AI. TDXdown and Heckler attacks hit TDX. HyperTheft extracts model weights via ciphertext side channels.AI / Vulnerability
2025 FebGoogle finds insecure hash in AMD microcode signature validation (CVE-2024-56161). Malicious microcode loadable under SEV-SNP.Vulnerability
2025 MayGoogle announces confidential GKE nodes with NVIDIA H100 GPUs. Confidential AI training and inference on GPU clusters.AI
2025 OctTEE.Fail. $1K DDR5 bus interposer extracts attestation keys from Intel TDX and AMD SEV-SNP. Attestation forgery demonstrated.Vulnerability
2025 DecIDC survey: 75% of organizations adopting confidential computing, 84% cite attestation validation as top challenge. Gartner predicts 75% of untrusted-infra processing uses CC by 2029.Institutional
2025 DecIETF RATS CoRIM reaches draft-09. Reference value format standards mature. Vendor adoption of publishing measurements remains minimal.Institutional
2026 JanStackWarp (CVE-2025-29943). Stack Engine synchronization bug enables deterministic stack pointer manipulation inside SEV-SNP guest via MSR toggling. Affects AMD Zen 1 through Zen 5. USENIX Security 2026.Vulnerability
2026TDXRay (IEEE S&P 2026). Reconstructs LLM user prompts word-for-word from encrypted TDX VMs by monitoring tokenizer cache access patterns. No crypto broken. UC San Diego, CISPA, Google.AI / Vulnerability
2026 MarNVIDIA publishes zero-trust AI factory reference architecture. CPU TEE + confidential GPU + CoCo + KBS. Model weights encrypted until attestation passes.AI
2026 Mar 31Ermolov extracts SGX Global Wrapping Key from Intel Gemini Lake. Root key extraction via arbitrary microcode. Unpatchable (hardware fuses).Vulnerability

Trusted Platform Modules: Boot Integrity and System State

The idea that hardware should measure and attest to software integrity goes back to the late 1990s. The Trusted Computing Group, formed in 2003, standardized the Trusted Platform Module, a discrete chip that stores cryptographic keys and maintains Platform Configuration Registers recording the boot chain as a sequence of hash measurements.

The TPM was designed to solve a specific problem: bootloader-level attacks. Rootkits and bootkits that compromised the system before the OS loaded were invisible to any software-based security tool. The TPM sat below the OS, measuring each boot stage before execution. It could answer a question that no operating system could answer about itself: did this machine boot the software it was supposed to boot?

Each boot stage measures the next before handing off execution. The measurements are extended into PCRs using a one-way hash chain: PCR_new = Hash(PCR_old || measurement). The TPM can produce a signed quote of its PCR values, and a remote verifier can check whether the system booted the expected software stack.

TPMs shipped in millions of enterprise laptops and servers. BitLocker used TPM-sealed keys for disk encryption. Linux distributions added measured boot support. But TPMs never achieved the broad security impact their designers envisioned. The problem was practical: to verify a TPM quote, you need to know what the correct PCR values should be, and nobody built the infrastructure to distribute and maintain those reference values at scale.

The TPM could tell you what booted. It could not tell you whether what booted was good.

What TPMs did accomplish was laying the conceptual groundwork for everything that followed. Hardware root of trust, measurement chains, remote attestation, platform state quotes. All of this vocabulary originated in the TPM ecosystem. Modern CPU TEEs inherited these concepts even as their architectures diverged significantly from the TPM model.

Hardware-Isolated Execution: Older Than You Think

Running code inside a tamper-resistant hardware boundary did not start with Intel or Apple. It started with smart cards.

Smart cards emerged in the late 1960s as special-purpose computers embedded in plastic cards. By the 1980s, they were executing cryptographic operations in banking, telecommunications, and government ID. A smart card is a tiny computer with its own processor, memory, and operating system, running inside a tamper-resistant package. That is a trusted execution environment by any reasonable definition, even if nobody called it that at the time.

HSMs extended the same concept to server-class computing. IBM’s 4758, commercially available in the late 1990s, provided a tamper-responding enclosure with its own processor, battery-backed memory, and secure boot chain. If someone tried to open the case, drill through it, or expose it to extreme temperatures, the device would zeroize its keys. The 4758 ran arbitrary code inside the boundary.

nCipher (founded 1996, later acquired by Thales) took this further with CodeSafe on the nShield HSM line, a development framework for deploying custom applications inside the HSM. This was general-purpose computation inside a hardware trust boundary, exactly the model that SGX would later attempt to replicate in silicon without a separate physical device. I spent years working with these HSMs. They ran custom signing logic, policy engines, tokenization routines, and key derivation functions, all inside the tamper-resistant module where the host OS could not observe or interfere.

The difference between these earlier systems and modern confidential computing is not the concept. It is the integration point. Smart cards and HSMs are discrete devices with well-defined physical boundaries. You can see the trust boundary. You can hold it in your hand. SGX, TDX, and SEV moved the trust boundary inside the CPU itself, eliminating the separate device but also eliminating the physical clarity. When the trust boundary is a set of microarchitectural state bits inside a processor with billions of transistors and a microcode layer updated quarterly, the attack surface becomes much larger.

Apple’s Secure Enclave Processor, introduced with the iPhone 5s in 2013, sat between these two models. It was a physically separate processor on the SoC with its own encrypted memory, dedicated to protecting biometric data and cryptographic keys. Even a fully compromised application processor with root privileges could not reach the Secure Enclave’s memory.

The SEP succeeded where HSMs had stayed confined to data centers for two reasons. It was invisible to users. Nobody configured it or provisioned it. And it protected something users cared about: their fingerprints and their money. The security was a means to a consumer feature, not a product in itself.

Intel SGX: Designed for the Desktop

Intel SGX, introduced with Skylake processors in 2015, brought the enclave concept to general-purpose computing. Instead of a separate processor, SGX created isolated memory regions within the main CPU. Code and data inside an enclave are encrypted in memory and protected from all other software on the system. The enclave’s measurement (MRENCLAVE) is a hash of exactly what was loaded, making attestation straightforward. One binary, one deterministic hash.

SGX was designed for the desktop. Its primary use cases were single-tenant scenarios like content protection, DRM key management, and Ultra HD Blu-ray playback. The threat model is clear. One machine, one user, and the enclave protects the content owner’s code from that user.

This is a single-tenant threat model. The attacker is the machine owner. There is no hypervisor. There are no co-tenant workloads competing for shared microarchitectural resources. The side-channel attack surface exists, but the economic incentive is limited. The attacker gains access to one DRM key or one media stream.

Enterprise adoption beyond DRM was limited. SGX enclaves had severe memory constraints (initially 128MB). Programming for SGX required partitioning applications into trusted and untrusted components. Intel deprecated SGX from consumer processors in 2021. The desktop DRM use case was not enough to sustain the technology.

Cloud Adoption and the Threat Model Mismatch

The cloud introduced a fundamentally different threat model, and this is where the problems began.

In the desktop DRM model, you protect your code from one user on one machine. In the cloud, you protect your code and data from the infrastructure provider, co-tenant workloads, the hypervisor, firmware, and anyone with physical access to a shared data center. The provider controls the hardware, the hypervisor, the firmware, the physical facility, and the scheduling of workloads across shared CPU cores.

The industry took technologies designed for the desktop single-tenant model and applied them to this multi-tenant cloud model. The architectural mismatch opened attack surfaces that the original designs did not anticipate.

SGX on a desktop shares caches, branch predictors, execution ports, and power delivery with the enclave owner’s own code. On a cloud server, those same resources are shared with co-tenant workloads controlled by different parties, each potentially adversarial. Cache-timing attacks that were theoretical on a desktop became practical in the cloud because the attacker could run arbitrary code on the same physical core. The side-channel catalog that accumulated against SGX from 2017 onward was not a series of implementation bugs. It was a consequence of deploying a single-tenant design in a multi-tenant environment.

AMD SEV and Intel TDX were designed with the cloud threat model more explicitly in mind, protecting entire virtual machines rather than individual enclaves. But they still share fundamental hardware resources with the hypervisor and co-tenants. CPU caches, memory buses, power delivery, and microarchitectural scheduling state. CacheWarp, StackWarp, WeSee, and Heckler all exploit the interfaces between the confidential VM and the hypervisor that manages it.

Virtual TPMs are another instance of the same pattern. Physical TPMs provide hardware-rooted trust because they are discrete chips with their own silicon. A vTPM is software running inside the hypervisor or a confidential VM. Cloud providers adopted vTPMs because provisioning hardware TPMs per VM is impractical at scale. The vTPM’s trust root is the software stack that hosts it. If the hypervisor is compromised, the vTPM is compromised.

The Repurposing Pattern

This is a recurring pattern in security technology, and it is one I have watched play out multiple times in my career. Build X for threat model Y, then repurpose X for threat model Z because X already exists and deploying it is cheaper than building something new.

SMS was designed for person-to-person messaging. It was repurposed for two-factor authentication because every phone could receive an SMS. The threat model assumed the cellular network was trusted. SIM swapping, SS7 interception, and malware-based SMS capture exploited the gap between “messaging channel” and “authentication channel.” NIST deprecated SMS-based 2FA. SMS OTP is still everywhere because deployment inertia exceeds the security community’s ability to move the market.

SSL was designed for securing web browsing sessions. It was repurposed for API authentication, IoT device communication, email encryption, and VPN tunneling. Each repurposing exposed assumptions in the original design that did not hold in the new context. The ecosystem spent two decades fixing the gaps through Certificate Transparency, HSTS, and progressively stricter CA/Browser Forum requirements. I was part of that ecosystem. The fixes were not inevitable. They required sustained institutional effort.

TPMs were designed for boot integrity on enterprise desktops. They were repurposed as vTPMs for cloud VM attestation, trading hardware isolation for scalability. SGX was designed for desktop DRM. It was repurposed for cloud confidential computing, trading single-tenant simplicity for multi-tenant attack surface. Each repurposing followed the same logic. The technology existed, the market needed something, and “available now with known limitations” beat “purpose-built but years away.”

The repurposed technology works well enough to create adoption. The adoption creates dependency. The dependency makes it difficult to replace even after the threat model gap is well understood. And the security research community spends years documenting the consequences while the market continues deploying.

AWS took a different path with Nitro Enclaves. Rather than building on CPU instruction extensions designed for desktops, Nitro Enclaves are isolated virtual machines on a purpose-built hypervisor with no persistent storage, no network access, and no access from the host. The Nitro model sidestepped many of the shared-resource problems because the hypervisor is minimal and the enclave has dedicated resources. The measurement model is clean. One image, one deterministic measurement.

Azure and GCP followed with confidential VM offerings on AMD SEV-SNP and Intel TDX. Google has positioned confidential computing as foundational to AI, expanding support across Confidential VMs, Confidential GKE Nodes, and Confidential Space with Intel TDX and NVIDIA H100 GPUs.

NVIDIA entered with confidential GPU support on H100 and Blackwell architectures. Their reference architecture for “zero-trust AI factories” combines CPU TEEs with confidential GPUs, Confidential Containers via Kata, and a Key Broker Service that releases model decryption keys only after remote attestation succeeds. Model weights remain encrypted until the hardware proves the enclave is genuine. This positions confidential computing as IP protection for model owners deploying on infrastructure they do not control.

Intel launched Trust Authority as a SaaS attestation service independent of the cloud provider. If the cloud provider both runs your TEE and verifies its attestation, you are still trusting the provider. An independent verifier breaks that circularity.

By 2025, every major hardware vendor and every major cloud provider had a confidential computing offering. The question was no longer whether the technology existed. It was whether anyone could make it work at scale.

Why It Never Hit Mass Adoption

Despite the investment, confidential computing did not achieve mass adoption through the SGX era or the first wave of confidential VMs. Several problems compounded.

Attestation is hard to operationalize. The verification step requires infrastructure that most organizations do not have and that the ecosystem has not built. I wrote about this problem in detail in Why Nobody Can Verify What Booted Your Server. The short version: 84% of IT leaders cite attestation validation as their top adoption challenge.

The performance overhead was non-trivial in early implementations. SGX had significant costs from enclave transitions and limited memory. Confidential VMs with SEV-SNP and TDX reduced this to single-digit percentage overhead for most workloads, but the perception of “secure means slow” persisted.

The developer experience was poor. SGX required application partitioning and a specialized SDK. Confidential VMs improved this by running unmodified applications, but attestation integration, key management, and secret provisioning still required specialized knowledge. As of early 2026, deploying a confidential workload still requires expertise that most teams do not have.

The vulnerability narrative undermined confidence. The side-channel attacks against SGX were not random bugs. They were a predictable consequence of deploying a single-tenant design in a multi-tenant environment. Each new attack generated press coverage and reinforced the perception that the technology could not deliver. Security teams found a long list of CVEs, academic attacks, and “known limitations” that made the risk-benefit calculus uncertain.

And without AI, the use cases were niche. DRM, financial services MPC, healthcare analytics, sovereign cloud compliance. Real markets, but not mass markets. Not enough volume to drive the ecosystem maturity needed for broad adoption.

The Vulnerability Record

The side-channel attacks did not stop with SGX’s partial deprecation. They followed the technology into the cloud.

Intel TDX still shares microarchitectural resources with the hypervisor. TDXdown demonstrated single-stepping and instruction counting against TDX trust domains. PortPrint showed that CPU port contention reveals distinctive execution signatures across SGX, TDX, and SEV alike, and because it exploits instruction-level parallelism rather than thread-level parallelism, disabling SMT does not help.

The attack that most directly undermines the “Private AI” narrative is TDXRay (IEEE S&P 2026, UC San Diego, CISPA, Google). TDXRay produces cache-line-granular memory access traces of unmodified, encrypted TDX VMs. The researchers reconstructed user prompts word-for-word from a confidential LLM inference session. No cryptography was broken. The attack works because standard LLM tokenizers traverse a hash map to find token IDs, and that traversal creates a memory access pattern observable at 64-byte cache-line resolution. The host watches which hash map nodes the tokenizer visits and stitches the prompt back together. The encryption protects the data in memory. The computation pattern leaks it through the cache.

TEE.Fail (ACM CCS 2025) is the most dramatic recent finding. Researchers built a $1,000 physical interposer that monitors the DDR5 memory bus and extracted ECDSA attestation keys from Intel’s Provisioning Certification Enclave, the keys that underpin the entire SGX and TDX attestation chain. Attestation can be forged. The attack requires physical access, which limits applicability. But cloud providers have physical access to every server they operate.

On March 31, 2026, Mark Ermolov announced the extraction of the SGX Global Wrapping Key from Intel Gemini Lake. This is not a side-channel leak. It is extraction of the root cryptographic key that protects SGX sealing operations. The key wraps Fuse Key 0, which means the entire key hierarchy rooted in hardware fuses is compromised for that platform generation. No microcode update can change fuses. Ermolov’s assessment: “its fundamental break means that the HW Root of Trust approach is not unshakable.”

Gemini Lake is a low-power consumer chip, not a Xeon server processor. The same attack has not been demonstrated on current server-class implementations. But the research trajectory is clear. Each generation of hardware trust primitives has been broken by the next generation of hardware security research.

Why the Pattern Persists: Five Broken Design Assumptions

The vulnerability record is not a collection of unrelated bugs. It is the predictable result of specific design assumptions that held in the original use cases but fail in the cloud and AI contexts where the technology is now deployed.

The attacker does not share physical hardware with the victim. SGX was designed for a desktop where one user runs one workload. In the cloud, co-tenants share CPU cores, caches, branch predictors, TLBs, execution ports, memory controllers, and power delivery. CacheWarp, StackWarp, and TDXRay all exploit resources that remain shared because complete resource partitioning would make the hardware unusable for general-purpose computing.

The platform owner is not the adversary. TPMs and early SGX assumed the platform owner was the user or a trusted IT department. In the cloud, the provider controls the hypervisor, firmware, BMC, physical facility, and scheduling. The interfaces between the TEE and the provider-controlled environment become the attack surface. WeSee, Heckler, and SEVered exploit these interfaces. TEE.Fail exploits the provider’s physical access to the memory bus.

The hardware root of trust is immutable. The attestation model depends on root keys being beyond the reach of software attacks. This assumption has been violated repeatedly. Ermolov reached fuse-based keys through microcode. Google’s CVE-2024-56161 found an insecure hash in AMD’s microcode signature validation. Sinkclose provided universal Ring-2 escalation on AMD CPUs back to 2006.

Attestation verification is someone else’s problem. The specifications define how to produce attestation evidence but not how to verify it at scale. In the desktop DRM case, one binary produced one hash. In the cloud, PCR values are combinatorial across firmware, bootloader, kernel, and boot configuration.

Performance and security tradeoffs are invisible. On a desktop running DRM playback, a 5% performance hit is imperceptible. On a cloud server running AI inference at scale, every percentage point is cost. Disabling SMT, applying Downfall mitigations, and enabling inline encryption all have measurable overhead. Organizations are pressured to disable countermeasures for performance, reopening the attack surface.

These assumptions compound. The attacker shares hardware with a platform owner who is the adversary, exploiting a hardware root of trust that has a shelf life, verified through attestation infrastructure that does not exist at scale, with mitigations that carry performance costs the deployment context cannot absorb. No single patch addresses the compound effect. The assumptions are architectural, not implementational, which is why the vulnerability catalog grows despite continuous investment in mitigations.

The full root cause analysis with specific attack mappings for each assumption is in the companion TEE Vulnerability Taxonomy.

AI Changes the Calculus

All of the problems described above are real and unresolved. None of them are stopping adoption, because AI changed the calculus.

Model weights represent billions of dollars in training investment. A leaked foundation model is a competitive catastrophe. Running inference on shared cloud infrastructure means trusting the cloud provider not to inspect memory, which is the exact problem TEEs solve.

Training data includes regulated information across healthcare, financial services, and government. The EU AI Act, DORA, CCPA, and evolving federal privacy frameworks create compliance pressure that confidential computing directly addresses.

Multi-party AI scenarios (federated learning, collaborative training, secure inference on third-party data) require environments where no single party sees the complete dataset. TEEs provide the isolation boundary. This is why every major hyperscaler is building on confidential computing despite its known limitations.

But AI workloads amplify every weakness. GPU TEEs are new and their attestation models are immature. The attestation chain now spans CPU TEE, GPU TEE, and potentially TPM, each with different measurement schemes. AI workloads run on heterogeneous infrastructure across multiple cloud providers. And AI workloads are the most valuable targets for the attacks TEEs are vulnerable to. An attacker who extracts model weights via a side channel gets a multi-billion-dollar asset.

The market treats the different TEE designs (SGX, SEV, TDX, Nitro, NVIDIA confidential GPU) as interchangeable. They are not. Each has different properties and different security guarantees. Pretending otherwise is how organizations end up deploying against a threat model their chosen TEE was not designed to address.

The Trust Model Gap

The deeper issue is the gap between what is marketed and what is engineered.

Confidential computing marketing says “even the infrastructure provider cannot access your data.”

The engineering reality is different. The infrastructure provider cannot access your data through the software stack, but the hardware has known side-channel leakages that a sufficiently motivated attacker with privileged access can exploit. The attestation infrastructure that proves the TEE is genuine has structural limitations that make verification at scale dependent on each organization building its own reference value databases. And the hardware root of trust that anchors the entire system has a demonstrated shelf life.

This is a reasonable tradeoff for many threat models. Most organizations are defending against curious administrators, software-level compromise, and regulatory compliance requirements. Side-channel attacks require significant expertise and often physical access. But the market does not present it as a tradeoff.

What Needs to Happen

Closing the gap between the market narrative and the engineering reality requires work that is less exciting than launching new AI services.

Firmware and OS vendors need to publish reference measurements. The standards exist. CoRIM provides the format. RFC 9683 provides the framework. What is missing is the operational commitment to publish signed measurement values for every release. I wrote about the infrastructure that would need to exist and why none of it does yet.

The industry needs honest threat modeling that acknowledges what TEEs protect against and what they do not. TEE.Fail requires physical access, but cloud providers have physical access to every server. TDXdown requires a malicious hypervisor, which is precisely the threat TDX is designed to defend against. These are not edge cases. They are the threat model.

Attestation verification needs to become a commodity. Organizations should not need to build their own reference value databases, write their own event log parsers, and maintain their own golden image registries. This infrastructure should be as standardized and available as Certificate Transparency logs are for the web PKI.

And the security research community’s findings need to be incorporated into the market narrative rather than treated as exceptions. The pattern of continuous vulnerability discovery and mitigation is the normal state of the technology, not an aberration.

Confidential computing is directionally correct. The ability to verify what code is running on hardware you do not control, rather than simply trusting the operator, is a fundamental improvement in how we build systems. Signal proved the model works. The challenge is closing the gap between that promise and the current engineering reality.

The organizations deploying confidential computing for AI workloads today should understand what they are buying. Against the threats they are most likely to face, curious administrators, software-level compromise, regulatory compliance gaps, and unauthorized data access by the infrastructure operator, confidential computing is a significant improvement. Against a well-resourced attacker with physical access to the hardware, side-channel expertise, or the ability to exploit a hardware root-of-trust vulnerability, it is a partial mitigation, not an absolute guarantee.

That is a defensible position. It is just not the one being marketed.


For practical guidance on deployment, see Confidential Computing: What It Is, What It Isn’t, and How to Think About It.

For the full vulnerability catalog and root cause framework, see the TEE Vulnerability Taxonomy and TPM Attestation and PCR Verification .

Previously: TPMs, TEEs, and Everything In Between (March 2025). See also: Why Nobody Can Verify What Booted Your Server.